实体链接与消歧
NER 找到了 "Paris"。实体链接来定夺:是法国巴黎?Paris Hilton?德州的 Paris?还是特洛伊王子帕里斯?不做链接,你的知识图谱就一直含混。
类型: Build 语言: Python 前置要求: Phase 5 · 06(NER)、Phase 5 · 24(共指消解) 预计时间: ~60 分钟
问题背景
一句话写道:"Jordan beat the press."。你的 NER 把 "Jordan" 标成 PERSON。好。但是哪个 Jordan?
- Michael Jordan(篮球)?
- Michael B. Jordan(演员)?
- Michael I. Jordan(伯克利的 ML 教授——没错,这种混淆在 ML 论文里真实存在)?
- Jordan(这个国家)?
- Jordan(一个希伯来名字)?
实体链接(EL)把每个提及消解到知识库里的唯一条目:Wikidata、Wikipedia、DBpedia,或你的领域 KB。两个子任务:
- 候选生成。 给定 "Jordan",哪些 KB 条目说得通?
- 消歧。 给定上下文,哪个候选是对的?
两步都可学习。两步都有基准。组合后的流水线稳定了十年——变的是消歧器的质量。
核心概念
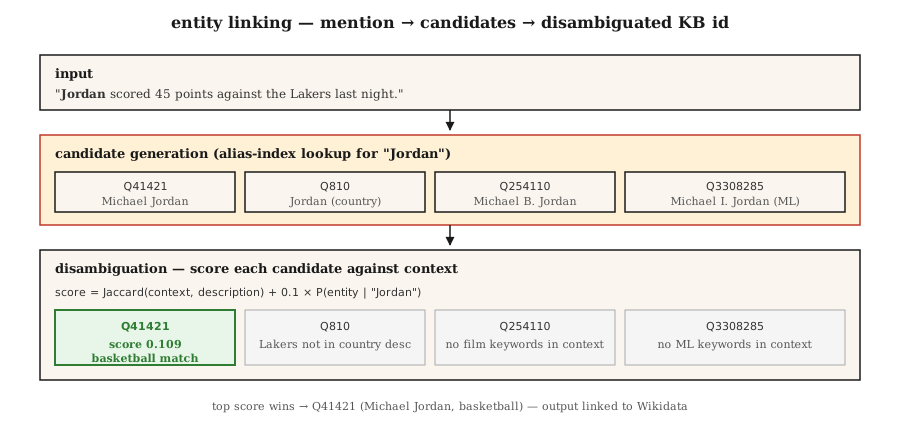
候选生成。 给定提及的表面形式("Jordan"),在别名索引里查候选。Wikipedia 别名词典覆盖大多数命名实体:"JFK" → John F. Kennedy、Jacqueline Kennedy、JFK 机场、JFK(电影)。典型索引每个提及返回 10-30 个候选。
消歧:三种方法。
- 先验 + 上下文(Milne & Witten,2008)。
P(entity | mention) × context-similarity(entity, text)。效果好,快,无需训练。 - 基于 embedding(ESS / REL / Blink)。 编码提及 + 上下文。编码每个候选的描述。取最大余弦。2020-2024 年的默认。
- 生成式(GENRE,2021;基于 LLM,2023+)。 逐 token 解码实体的规范名。约束到一棵有效实体名的字典树,保证输出一定是有效的 KB id。
端到端 vs 流水线。 现代模型(ELQ、BLINK、ExtEnD、GENRE)一趟跑完 NER + 候选生成 + 消歧。流水线系统在生产里仍占主导,因为你能替换组件。
两项测量
- 提及召回(候选生成)。 正确 KB 条目出现在候选列表里的金标准提及所占比例。整条流水线的地板线。
- 消歧准确率 / F1。 给定正确候选,top-1 正确的频率。
永远两个都报。一个在 80% 候选召回上做到 99% 消歧的系统,是一条 80% 的流水线。
gx-entity-linking动手构建
第 1 步:从 Wikipedia 重定向构建别名索引
alias_to_entities = {
    "jordan": ["Q41421 (Michael Jordan)", "Q810 (Jordan, country)", "Q254110 (Michael B. Jordan)"],
    "paris":  ["Q90 (Paris, France)", "Q663094 (Paris, Texas)", "Q55411 (Paris Hilton)"],
    "apple":  ["Q312 (Apple Inc.)", "Q89 (apple, fruit)"],
}
Wikipedia 别名数据:约 1800 万对 (alias, entity)。从 Wikidata 转储下载。存成倒排索引。
第 2 步:基于上下文的消歧
def disambiguate(mention, context, alias_index, entity_desc):
    candidates = alias_index.get(mention.lower(), [])
    if not candidates:
        return None, 0.0
    context_words = set(tokenize(context))
    best, best_score = None, -1
    for entity_id in candidates:
        desc_words = set(tokenize(entity_desc[entity_id]))
        union = len(context_words | desc_words)
        score = len(context_words & desc_words) / union if union else 0.0
        if score > best_score:
            best, best_score = entity_id, score
    return best, best_score
这个 Jaccard 重叠是个玩具。换成 embedding 上的余弦相似度(transformer 版本见 code/main.py 的第 2 步)。
第 3 步:基于 embedding(BLINK 风格)
from sentence_transformers import SentenceTransformer
encoder = SentenceTransformer("sentence-transformers/all-MiniLM-L6-v2")

def embed_mention(text, mention_span):
    start, end = mention_span
    marked = f"{text[:start]} [MENTION] {text[start:end]} [/MENTION] {text[end:]}"
    return encoder.encode([marked], normalize_embeddings=True)[0]

def embed_entity(entity_id, description):
    return encoder.encode([f"{entity_id}: {description}"], normalize_embeddings=True)[0]
索引时,把每个 KB 实体编码一次。查询时,把提及 + 上下文编码一次,对候选池做点积,取最大。
第 4 步:生成式实体链接(概念)
GENRE 逐字符解码实体的 Wikipedia 标题。约束解码(见第 20 课)确保只能输出有效标题。和一棵 KB 支撑的字典树紧密集成。现代的后裔是 REL-GEN 和带结构化输出的 LLM 提示 EL。
prompt = f"""Text: {text}
Mention: {mention}
List the best Wikipedia title for this mention.
Respond with JSON: {{"title": "..."}}"""
配上一个白名单(Outlines choice),这是 2026 年最容易上线的 EL 流水线。
第 5 步:在 AIDA-CoNLL 上评估
AIDA-CoNLL 是标准 EL 基准:1393 篇路透社文章,3.4 万个提及,Wikipedia 实体。报告 KB 内准确率(P@1)和 KB 外 NIL 检测率。
坑
- NIL 处理。 有些提及不在 KB 里(新兴实体、冷门人物)。系统必须预测 NIL,而不是猜一个错误实体。单独测量。
- 提及边界错误。 上游 NER 漏掉部分 span("Bank of America" 只标成 "Bank")。EL 召回下降。
- 流行度偏见。 训练出来的系统过度预测高频实体。一篇 ML 论文里 "Michael I. Jordan" 的提及常被链到篮球的 Jordan。
- 跨语言 EL。 把中文文本里的提及映射到英语 Wikipedia 实体。需要多语言编码器或一个翻译步骤。
- KB 陈旧。 新公司、事件、人物不在去年的 Wikipedia 转储里。生产流水线需要一个刷新回路。
实际使用
2026 年的栈:
| 场景 | 选择 |
|---|---|
| 通用英语 + Wikipedia | BLINK 或 REL |
| 跨语言,KB = Wikipedia | mGENRE |
| LLM 友好,每天少量提及 | 用候选列表 + 约束 JSON 提示 Claude/GPT-4 |
| 领域专用 KB(医学、法律) | 自定义 BERT 配 KB 感知检索 + 在领域 AIDA 式集上微调 |
| 极低延迟 | 仅精确匹配先验(Milne-Witten 基线) |
| 研究 SOTA | GENRE / ExtEnD / 生成式 LLM-EL |
2026 年上线的生产模式:NER → 共指 → 对每个提及做 EL → 把簇塌缩成每簇一个规范实体。输出:文档里每个实体一个 KB id,而非每个提及一个。
拿去用
存为 outputs/skill-entity-linker.md:
---
name: entity-linker
description: Design an entity linking pipeline — KB, candidate generator, disambiguator, evaluation.
version: 1.0.0
phase: 5
lesson: 25
tags: [nlp, entity-linking, knowledge-graph]
---

Given a use case (domain KB, language, volume, latency budget), output:

1. Knowledge base. Wikidata / Wikipedia / custom KB. Version date. Refresh cadence.
2. Candidate generator. Alias-index, embedding, or hybrid. Target mention recall @ K.
3. Disambiguator. Prior + context, embedding-based, generative, or LLM-prompted.
4. NIL strategy. Threshold on top score, classifier, or explicit NIL candidate.
5. Evaluation. Mention recall @ 30, top-1 accuracy, NIL-detection F1 on held-out set.

Refuse any EL pipeline without a mention-recall baseline (you cannot evaluate a disambiguator without knowing candidate gen surfaced the right entity). Refuse any pipeline using LLM-prompted EL without constrained output to valid KB ids. Flag systems where popularity bias affects minority entities (e.g. name-clashes) without domain fine-tuning.
练习
- 简单。 在 10 个有歧义的提及(Paris、Jordan、Apple)上实现
code/main.py里的先验+上下文消歧器。手工标注正确实体。测准确率。 - 中等。 用一个 sentence transformer 编码 50 个有歧义的提及。给每个候选的描述做 embedding。把基于 embedding 的消歧和 Jaccard 上下文重叠对比。
- 困难。 建一个 1000 实体的领域 KB(比如你公司的员工 + 产品)。端到端实现 NER + EL。在 100 个留出句子上测精确率和召回率。
关键术语
| 术语 | 人们怎么说 | 它实际是什么 |
|---|---|---|
| 实体链接(EL) | 链到 Wikipedia | 把一个提及映射到唯一的 KB 条目。 |
| 候选生成 | 可能是谁? | 为一个提及返回一份说得通的 KB 条目短名单。 |
| 消歧 | 挑对的那个 | 用上下文给候选打分,挑出赢家。 |
| 别名索引 | 那张查找表 | 从表面形式 → 候选实体的映射。 |
| NIL | 不在 KB 里 | 明确预测没有 KB 条目匹配。 |
| KB | 知识库 | Wikidata、Wikipedia、DBpedia,或你的领域 KB。 |
| AIDA-CoNLL | 那个基准 | 1393 篇路透社文章,带金标准实体链接。 |
延伸阅读
- Milne, Witten (2008). Learning to Link with Wikipedia —— 奠基性的先验+上下文方法。
- Wu et al. (2020). Zero-shot Entity Linking with Dense Entity Retrieval (BLINK) —— 基于 embedding 的主力。
- De Cao et al. (2021). Autoregressive Entity Retrieval (GENRE) —— 带约束解码的生成式 EL。
- Hoffart et al. (2011). Robust Disambiguation of Named Entities in Text (AIDA) —— 基准论文。
- REL: An Entity Linker Standing on the Shoulders of Giants (2020) —— 开源生产栈。