pgvector ivfflat index-supported queries
You need to use the distance operator (<=>, <->, or <#>) matching the ops class you used during index creation in your ORDER BY clause. A canonical query would be:
===== PAGE: https://docs.tigerdata.com/ai/python-interface-for-pgvector-and-timescale-vector/ =====
Examples:
Example 1 (sql):
CREATE EXTENSION IF NOT EXISTS vector;
CREATE EXTENSION IF NOT EXISTS vectorscale;
Example 2 (sql):
CREATE TABLE IF NOT EXISTS document_embedding  (
    id BIGINT PRIMARY KEY GENERATED BY DEFAULT AS IDENTITY,
    document_id BIGINT FOREIGN KEY(document.id)
    metadata JSONB,
    contents TEXT,
    embedding VECTOR(1536)
)
Example 3 (sql):
SELECT *
FROM document_embedding
ORDER BY embedding <=> $1
LIMIT 10
Example 4 (sql):
SELECT *
FROM document_embedding
ORDER BY embedding <=> $1
LIMIT 10
User management
URL: llms-txt#user-management
Contents:
- Project members
- Adding project members
- Service users
- Adding service users
- Multi-factor user authentication
- Configuring multi-factor authentication
- User authentication tokens
You can add new users, and manage existing users, in MST Console. New users can be added to an entire project, or a single service.
You can invite new users to join your project as project members. There are several roles available for project members:
| Role | Invite more users | Modify billing information | Manage existing services | Start and stop services | View service information |
|---|---|---|---|---|---|
| Admin | ✅ | ✅ | ✅ | ✅ | ✅ |
| Operator | ❌ | ❌ | ✅ | ✅ | ✅ |
| Developer | ✅ | ❌ | ✅ | ❌ | ✅ |
| Read-only | ❌ | ❌ | ❌ | ❌ | ✅ |
Users who can manage existing services can create databases and connect to them, on a service that already exists. To create a new service, users need the start and stop services permission.
Adding project members
- [Sign in][mst-login] to your MST Console.
- Check that you are in the project that you want to change the members for, and click
Members. - In the
Project memberspage, type the email address of the member you want to add, and select a role for the member. - Click
Send invitation. - The new user is sent an email inviting them to the project, and the invite shows in the
Pending invitationslist. You can clickWithdraw invitationto remove an invitation before it has been accepted. - When they accept the invitation, the user details show in the
Memberslist. You can edit a member role by selecting a new role in the list. You can delete a member by clicking the delete icon in the list.
By default, when you create a new service, a new tsdbadmin user is created. This is the user that you use to connect to your new service.
The tsdbadmin user is the owner of the database, but is not a superuser. To access features requiring a superuser, log in as the postgres user instead.
The tsdbadmin user for Managed Service for TimescaleDBs can:
- Create a database
- Create a role
- Perform replication
- Bypass row level security (RLS)
This allows you to use the tsdbadmin user to create another user with any other roles. For a complete list of roles available, see the [Postgres role attributes documentation][pg-roles-doc].
Your service must be running before you can manage users.
Adding service users
- [Sign in][mst-login] to MST Console. By default, you start in the
Servicesview, showing any services you currently have in your project. - Click the name of the service that you want to add users to.
- Select
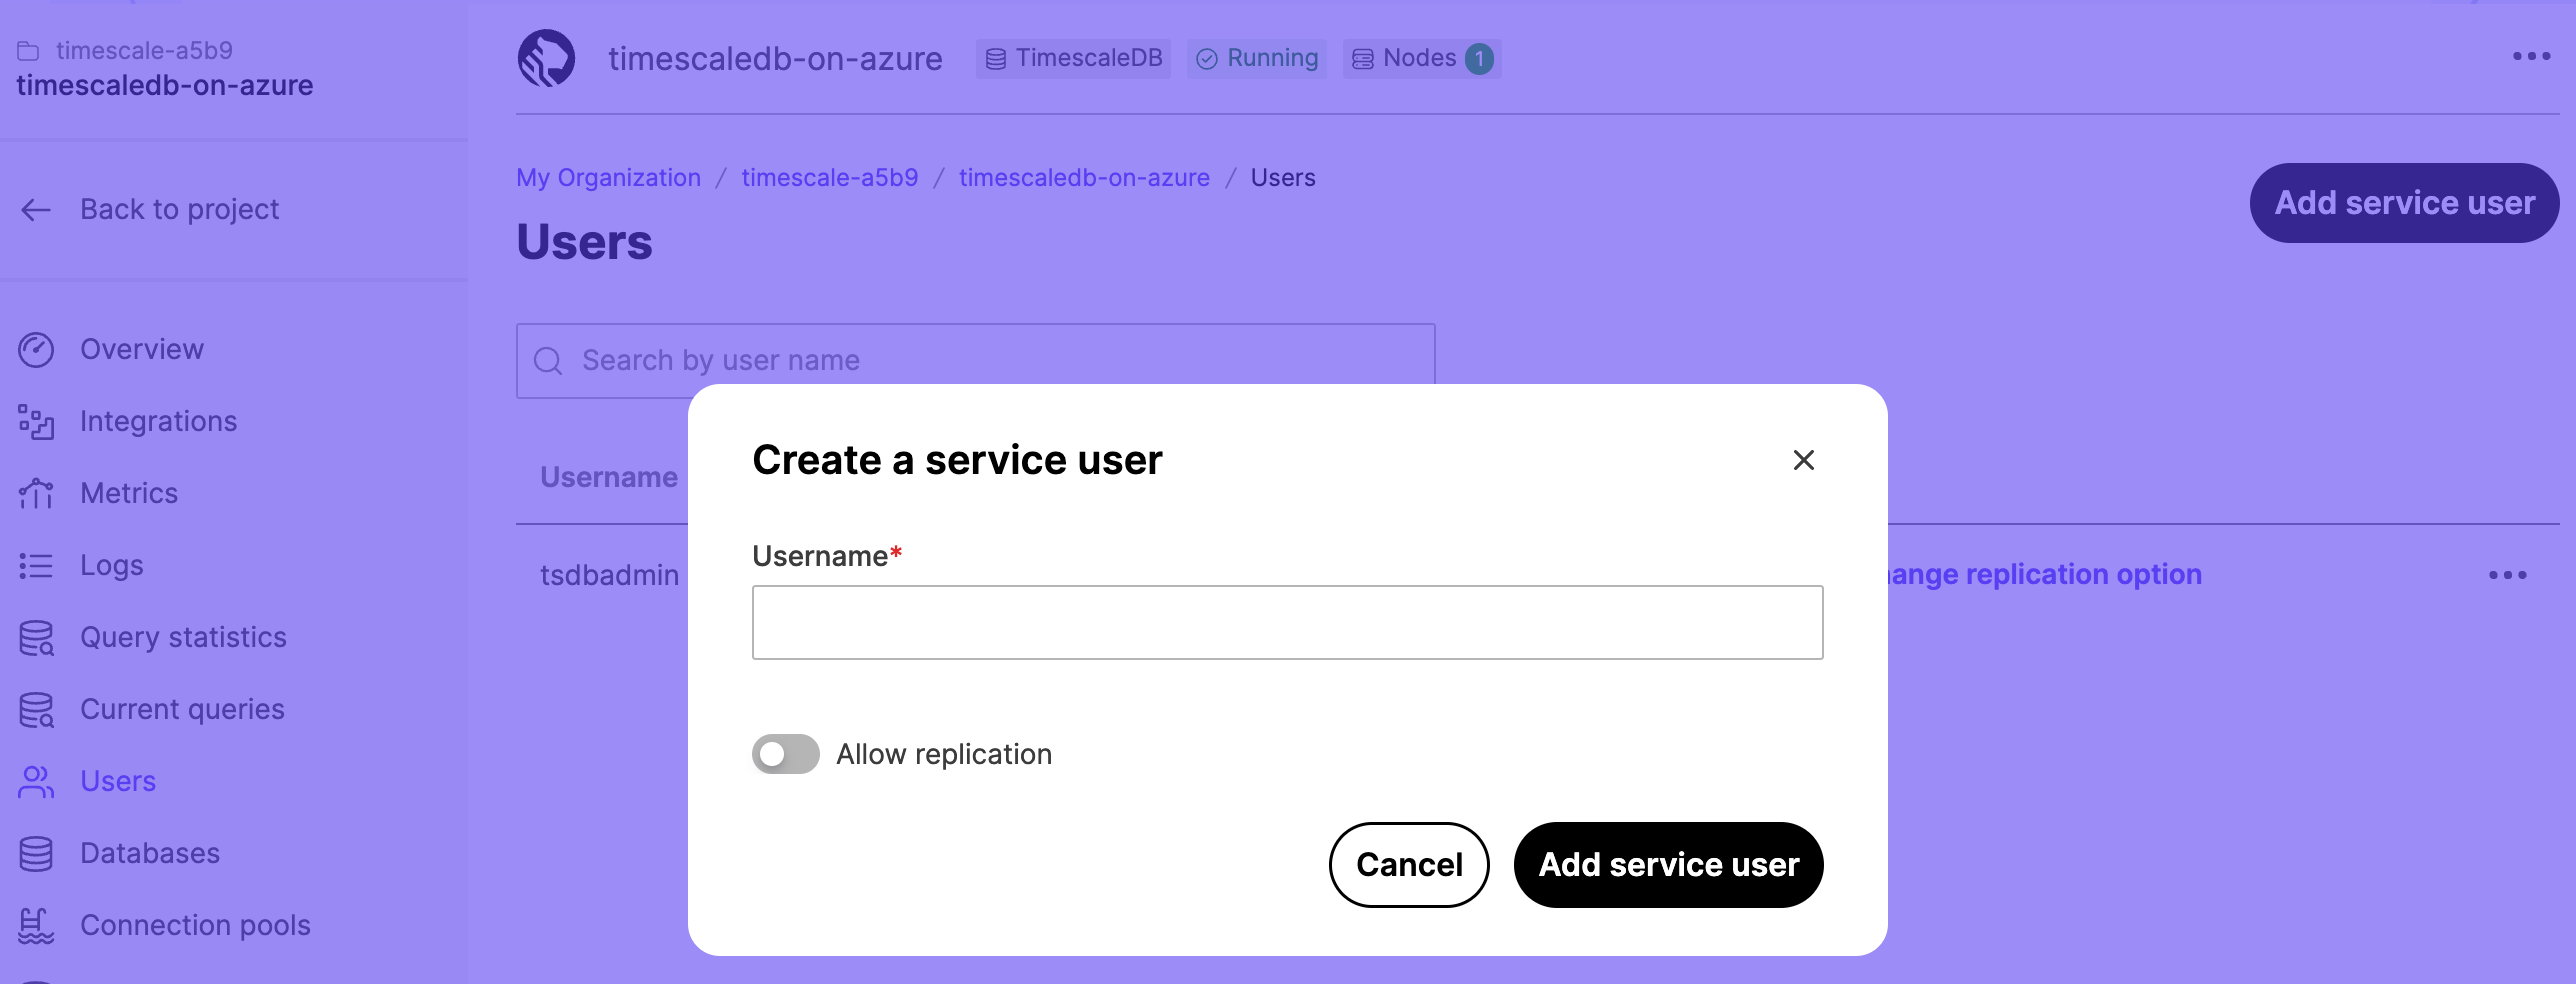
Users, then clickAdd service user:
- In the
Usernamefield, type a name for your user. If you want to allow the user to be replicated, toggleAllow replication. ClickAdd service userto save the user. - The new user shows in the
Usernamelist.
To view the password, click the eye icon. Use the options in the list to change the replication setting and password, or delete the user.
Multi-factor user authentication
You can use multi-factor authentication (MFA) to log in to MST Console. This requires an authentication code, provided by the Google Authenticator app on your mobile device.
You can see which authentication method is in use by each member of your Managed Service for TimescaleDB project. From the dashboard, navigate to the Members section. Each member is listed in the table with an authentication method of either Password or Two-Factor.
Before you begin, install the Google Authenticator app on your mobile device. For more information, and installation instructions, see [the Google Authenticator documentation][install-google-authenticator].
Configuring multi-factor authentication
- [Sign in][mst-login] to MST Console.
- Click the
User informationicon in the top-right of the dashboard to go to theUser profilesection. - In the
Authenticationtab, toggleTwo-factor authenticationtoEnabled, and enter your password. - On your mobile device, open the Google Authenticator app, tap
+and selectScan a QR code. - On your mobile device, scan the QR code provided by Managed Service for TimescaleDB.
- In your MST dashboard, enter the confirmation code provided by the Google Authenticator app, and click
Enable Two-Factor Auth.
If you lose access to the mobile device you use for multi-factor authentication, you cannot sign in to your Managed Service for TimescaleDB account. To regain access to your account, on the login screen, click Forgot password? and follow the step to reset your password. When you have regained access to your account, reconfigure multi-factor authentication.
User authentication tokens
Every time a registered user logs in, Managed Service for TimescaleDB creates a new authentication token. This occurs for login events using the portal, and using the API. By default, authentication tokens expire after 30 days, but the expiry date is adjusted every time the token is used. This means that tokens can be used indefinitely, if the user logs in at least every 30 days.
You can see the list of all current authentication tokens in the Managed Service for TimescaleDB dashboard. Sign in to your account, and click the User information icon in the top-right of the dashboard to go to the User profile section. In the Authentication tab, the table lists all current authentication tokens.
When you make authentication changes, such as enabling two factor authentication or resetting a password, all existing tokens are revoked. In some cases, a new token is immediately created so that the web console session remains valid. You can also manually revoke authentication tokens from the User profile page individually, or click Revoke all tokens to revoke all current tokens.
Additionally, you can click Generate token to create a new token. When you generate a token on this page, you can provide a description, maximum age, and an extension policy. Generating authentication tokens in this way allows you to use them with monitoring applications that make automatic API calls to Managed Service for TimescaleDB.
There is a limit to how many valid authentication tokens are allowed per user. This limit is different for tokens that are created as a result of a sign in operation, and for tokens created explicitly. For automatically created tokens, the system automatically deletes the oldest tokens as new ones are created. For explicitly created tokens, older tokens are not deleted unless they expire or are manually revoked. This can result in explicitly created tokens that stop working, even though they haven't expired or been revoked. To avoid this, make sure you sign out at the end of every user session, instead of just discarding your authentication token. This is especially important for automation tools that automatically sign in.
===== PAGE: https://docs.tigerdata.com/mst/billing/ =====
Configuring TimescaleDB
URL: llms-txt#configuring-timescaledb
Contents:
- Using
timescaledb-tune - Postgres configuration and tuning
- Memory settings
- Worker settings
- Disk-write settings
- Lock settings
- TimescaleDB configuration and tuning
- Policies
- Distributed hypertables
- Administration
TimescaleDB works with the default Postgres server configuration settings. However, we find that these settings are typically too conservative and can be limiting when using larger servers with more resources (CPU, memory, disk, etc). Adjusting these settings, either [automatically with our tool timescaledb-tune][tstune] or manually editing your machine's postgresql.conf, can improve performance.
You can determine the location of postgresql.conf by running SHOW config_file; from your Postgres client (for example, psql).
In addition, other TimescaleDB specific settings can be modified through the postgresql.conf file as covered in the [TimescaleDB settings][ts-settings] section.
Using timescaledb-tune
To streamline the configuration process, use [timescaledb-tune][tstune] that handles setting the most common parameters to appropriate values based on your system, accounting for memory, CPU, and Postgres version. timescaledb-tune is packaged along with the binary releases as a dependency, so if you installed one of the binary releases (including Docker), you should have access to the tool. Alternatively, with a standard Go environment, you can also go get the repository to install it.
timescaledb-tune reads your system's postgresql.conf file and offers interactive suggestions for updating your settings:
These changes are then written to your postgresql.conf and take effect on the next (re)start. If you are starting on fresh instance and don't feel the need to approve each group of changes, you can also automatically accept and append the suggestions to the end of your postgresql.conf like so:
Postgres configuration and tuning
If you prefer to tune the settings yourself, or are curious about the suggestions that timescaledb-tune makes, then check these. However, timescaledb-tune does not cover all settings that you need to adjust.
All of these settings are handled by timescaledb-tune.
The settings shared_buffers, effective_cache_size, work_mem, and maintenance_work_mem need to be adjusted to match the machine's available memory. Get the configuration values from the [PgTune][pgtune] website (suggested DB Type: Data warehouse). You should also adjust the max_connections setting to match the ones given by PgTune since there is a connection between max_connections and memory settings. Other settings from PgTune may also be helpful.
All of these settings are handled by timescaledb-tune.
Postgres utilizes worker pools to provide the required workers needed to support both live queries and background jobs. If you do not configure these settings, you may observe performance degradation on both queries and background jobs.
TimescaleDB background workers are configured using the timescaledb.max_background_workers setting. You should configure this setting to the sum of your total number of databases and the total number of concurrent background workers you want running at any given point in time. You need a background worker allocated to each database to run a lightweight scheduler that schedules jobs. On top of that, any additional workers you allocate here run background jobs when needed.
For larger queries, Postgres automatically uses parallel workers if they are available. To configure this use the max_parallel_workers setting. Increasing this setting improves query performance for larger queries. Smaller queries may not trigger parallel workers. By default, this setting corresponds to the number of CPUs available. Use the --cpus flag or the TS_TUNE_NUM_CPUS docker environment variable to change it.
Finally, you must configure max_worker_processes to be at least the sum of timescaledb.max_background_workers and max_parallel_workers. max_worker_processes is the total pool of workers available to both background and parallel workers (as well as a handful of built-in Postgres workers).
By default, timescaledb-tune sets timescaledb.max_background_workers to 16. In order to change this setting, use the --max-bg-workers flag or the TS_TUNE_MAX_BG_WORKERS docker environment variable. The max_worker_processes setting is automatically adjusted as well.
Disk-write settings
In order to increase write throughput, there are [multiple settings][async-commit] to adjust the behavior that Postgres uses to write data to disk. In tests, performance is good with the default, or safest, settings. If you want a bit of additional performance, you can set synchronous_commit = 'off'([Postgres docs][synchronous-commit]). Please note that when disabling synchronous_commit in this way, an operating system or database crash might result in some recent allegedly committed transactions being lost. We actively discourage changing the fsync setting.
TimescaleDB relies heavily on table partitioning for scaling time-series workloads, which has implications for [lock management][lock-management]. A hypertable needs to acquire locks on many chunks (sub-tables) during queries, which can exhaust the default limits for the number of allowed locks held. This might result in a warning like the following:
To avoid this issue, it is necessary to increase the max_locks_per_transaction setting from the default value (which is typically 64). Since changing this parameter requires a database restart, it is advisable to estimate a good setting that also allows some growth. For most use cases we recommend the following setting:
where num_chunks is the maximum number of chunks you expect to have in a hypertable and max_connections is the number of connections configured for Postgres. This takes into account that the number of locks used by a hypertable query is roughly equal to the number of chunks in the hypertable if you need to access all chunks in a query, or double that number if the query uses an index. You can see how many chunks you currently have using the [timescaledb_information.hypertables][timescaledb_information-hypertables] view. Changing this parameter requires a database restart, so make sure you pick a larger number to allow for some growth. For more information about lock management, see the [Postgres documentation][lock-management].
TimescaleDB configuration and tuning
Just as you can tune settings in Postgres, TimescaleDB provides a number of configuration settings that may be useful to your specific installation and performance needs. These can also be set within the postgresql.conf file or as command-line parameters when starting Postgres.