Highlighted features
Configurable sparse indexes: manually configure sparse indexes (min-max or bloom) on one or more columns of compressed hypertables, optimizing query performance for specific workloads and reducing I/O. In previous versions, these were automatically created based on heuristics and could not be modified.
UUIDv7 support: native support for UUIDv7 for both compression and partitioning. UUIDv7 embeds a time component, improving insert locality and enabling efficient time-based range queries while maintaining global uniqueness.
Vectorized UUID compression: new vectorized compression for UUIDv7 columns doubles query performance and improves storage efficiency by up to 30%.
UUIDv7 partitioning: hypertables can now be partitioned on UUIDv7 columns, combining time-based chunking with globally unique IDs—ideal for large-scale event and log data.
Multi-column SkipScan: expands SkipScan to support multiple distinct keys, delivering millisecond-fast deduplication and
DISTINCT ONqueries across billions of rows. Learn more in our blog post and documentation.Compression improvements: default
segmentbyandorderbysettings are now applied at compression time for each chunk, automatically adapting to evolving data patterns for better performance. This was previously set at the hypertable level and fixed across all chunks.
The experimental Hypercore Table Access Method (TAM) has been removed in this release following advancements in the columnstore architecture.
For a comprehensive list of changes, refer to the TimescaleDB 2.22 & 2.22.1 release notes.
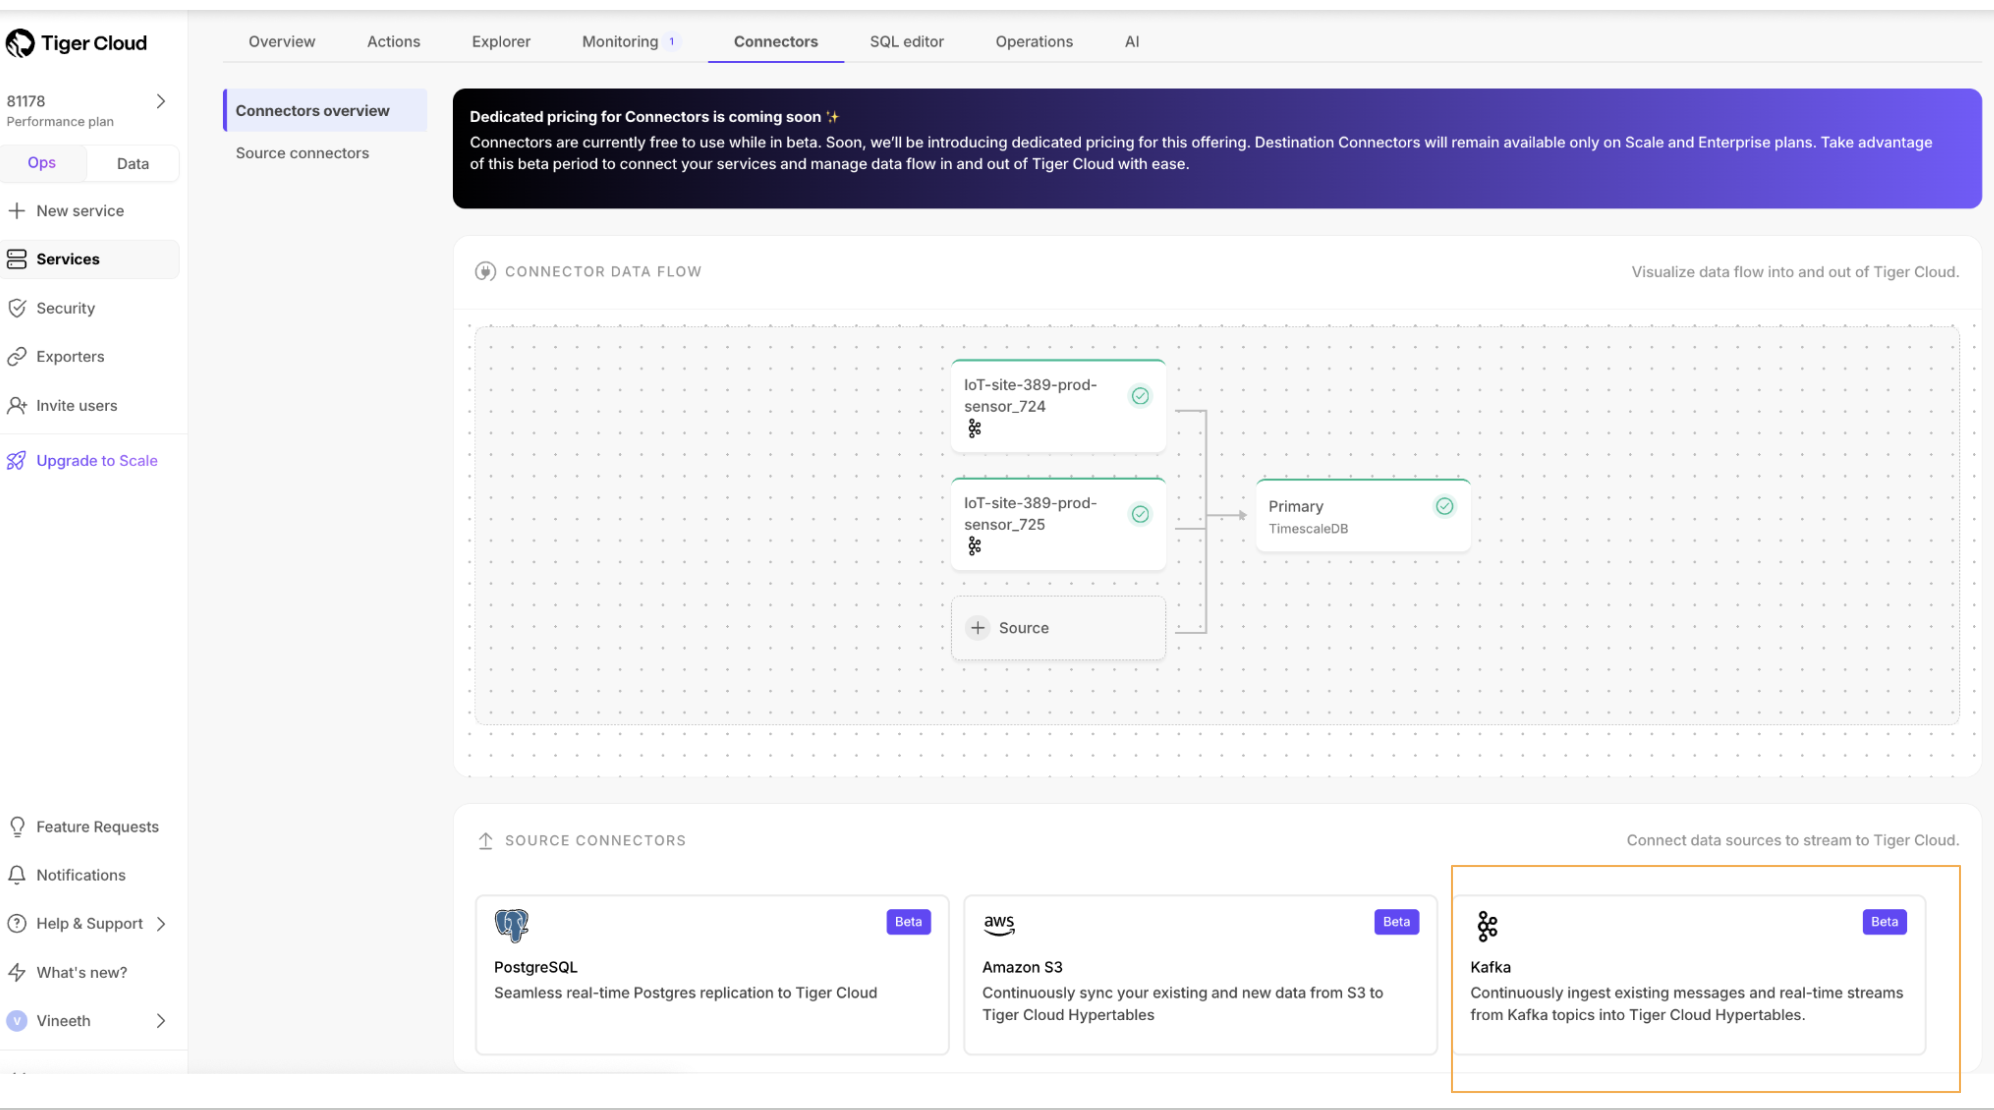
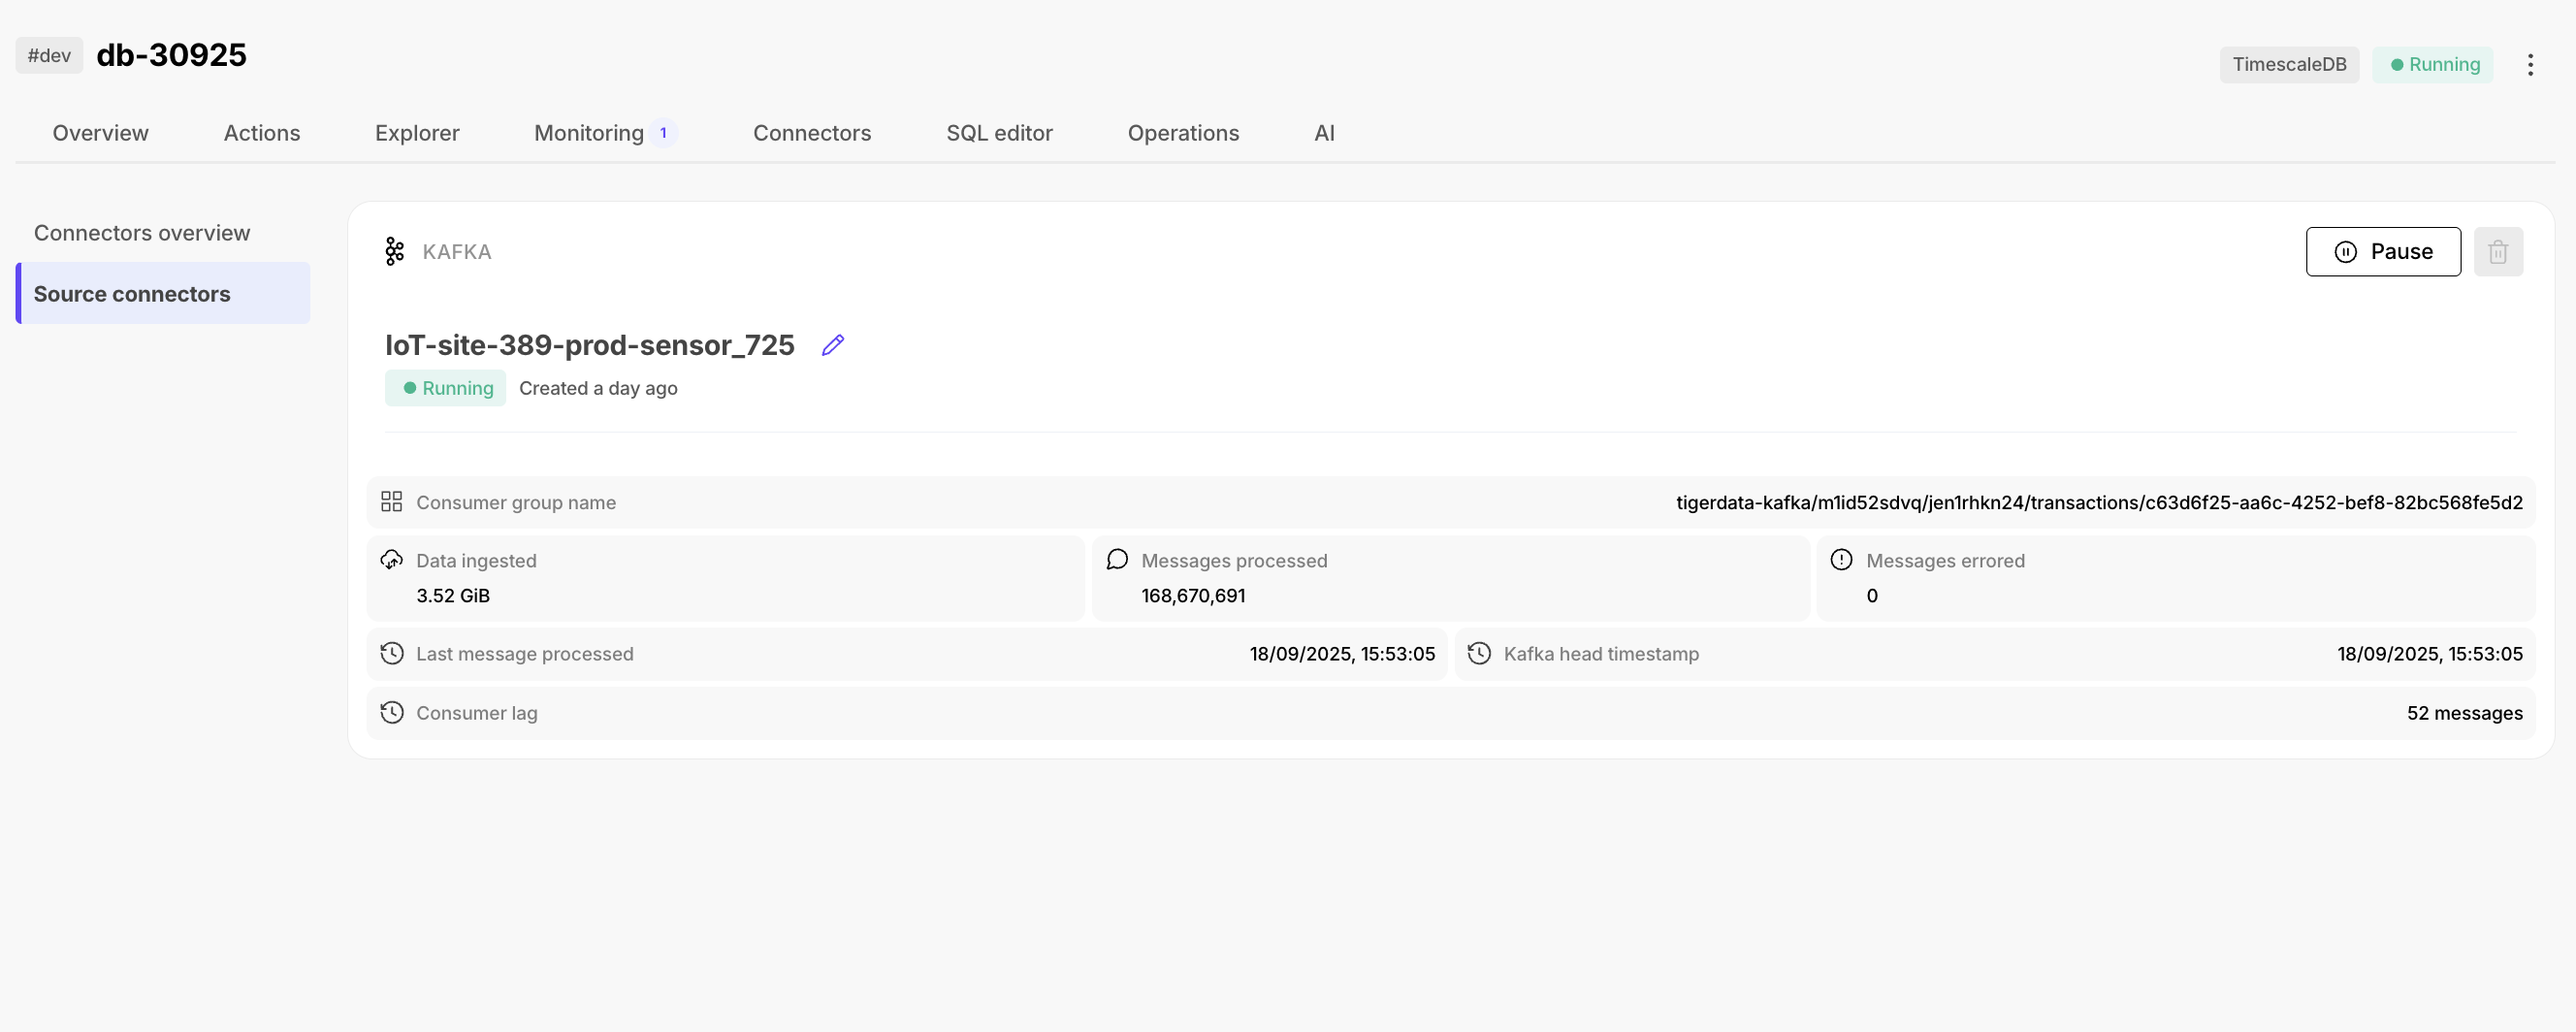
Kafka Source Connector (beta)
The new Kafka Source Connector enables you to connect your existing Kafka clusters directly to Tiger Cloud and ingest data from Kafka topics into hypertables. Developers often build proxies or run JDBC Sink Connectors to bridge Kafka and Tiger Cloud, which is error-prone and time-consuming. With the Kafka Source Connector, you can seamlessly start ingesting your Kafka data natively without additional middleware.
- Supported formats: AVRO
- Supported platforms: Confluent Cloud and Amazon Managed Streaming for Apache Kafka