Automatic document embeddings from S3
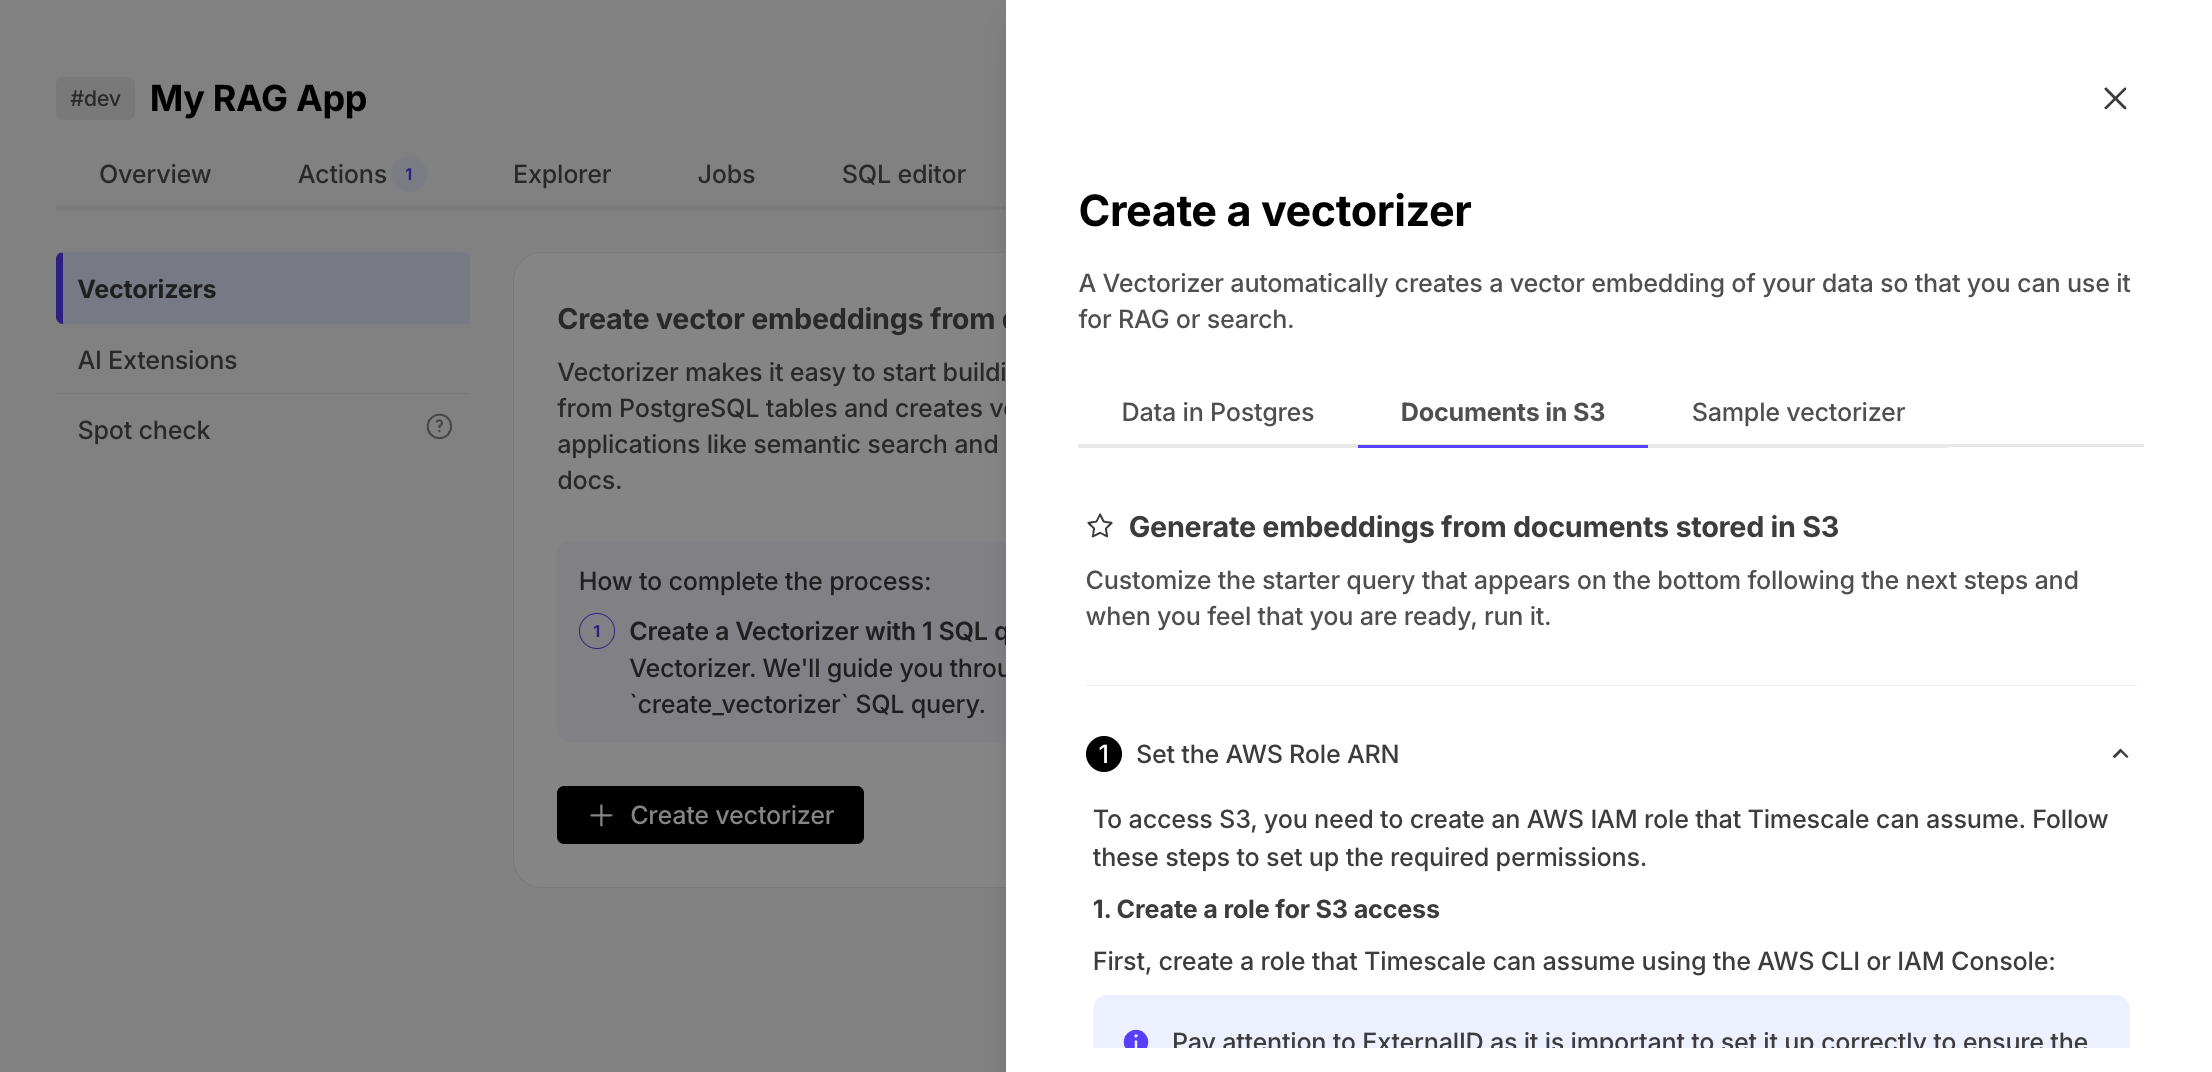
pgai vectorizer now supports automatic document vectorization. This makes it dramatically easier to build RAG and semantic search applications on top of unstructured data stored in Amazon S3. With just a SQL command, developers can create, update, and synchronize vector embeddings from a wide range of document formats—including PDFs, DOCX, XLSX, HTML, and more—without building or maintaining complex ETL pipelines.
Instead of juggling multiple systems and syncing metadata, vectorizer handles the entire process: downloading documents from S3, parsing them, chunking text, and generating vector embeddings stored right in Postgres using pgvector. As documents change, embeddings stay up-to-date automatically—keeping your Postgres database the single source of truth for both structured and semantic data.