14.2 TODO-Driven Research Paradigm
14.2.1 What is TODO-Driven Research
Traditional search engines can only answer single questions, while deep research needs to answer a series of related questions. The TODO-driven research paradigm decomposes complex research topics into multiple subtasks (TODOs), executes them one by one, and integrates the results.
The core idea of this paradigm is: Transform the complex task of "research" into a "planning → execution → integration" process.
Let's understand this transformation through an example. Suppose you want to research "What kind of organization is Datawhale?". The traditional search method is:
User input: What kind of organization is Datawhale?
Search engine: Returns 10-20 links
User: Click on links one by one, read content, take notes
Result: Fragmented information, lacking systematization
The problem with this approach is that each link only covers one aspect of the topic, lacks systematic structure, and requires manual organization and summarization.
TODO-Driven Approach: Systematic Research
User input: What kind of organization is Datawhale?

System planning:
  ├─ TODO 1: Basic information about Datawhale (organizational positioning)
  ├─ TODO 2: Main projects of Datawhale (core content)
  ├─ TODO 3: Community culture of Datawhale (values)
  └─ TODO 4: Influence of Datawhale (social contribution)

System execution:
  For each TODO:
    1. Search for relevant materials
    2. Summarize key information
    3. Record source citations

System integration:
  Generate structured report:
    ├─ Part 1: Organizational positioning (from TODO 1)
    ├─ Part 2: Core content (from TODO 2)
    ├─ Part 3: Values (from TODO 3)
    ├─ Part 4: Social contribution (from TODO 4)
    └─ References: All source citations
The advantages of this approach are that it decomposes complex topics into clear sub-questions, records search results and summaries for each subtask for easy traceability, and the systematic research process avoids missing important information. It's also easy to add new subtasks or adjust execution order.
A complete TODO-driven research system contains three core elements:
(1) Intelligent Planner (TODO Planner): Responsible for decomposing research topics into subtasks. A good planner needs to understand the key aspects and research objectives of the topic, decompose the topic into 3-5 subtasks (too few won't cover everything, too many will be redundant), and design appropriate search queries for each subtask.
(2) Task Executor: Responsible for executing each subtask. The executor needs to use search engines to obtain relevant materials, extract key information and remove redundant content, while saving all source citations for easy verification.
(3) Report Writer: Responsible for integrating the results of all subtasks. The generator needs to organize content in logical order, merge duplicate information, and add source citations for each viewpoint.
In our case, the TODO-driven research process is shown in Figure 14.5:
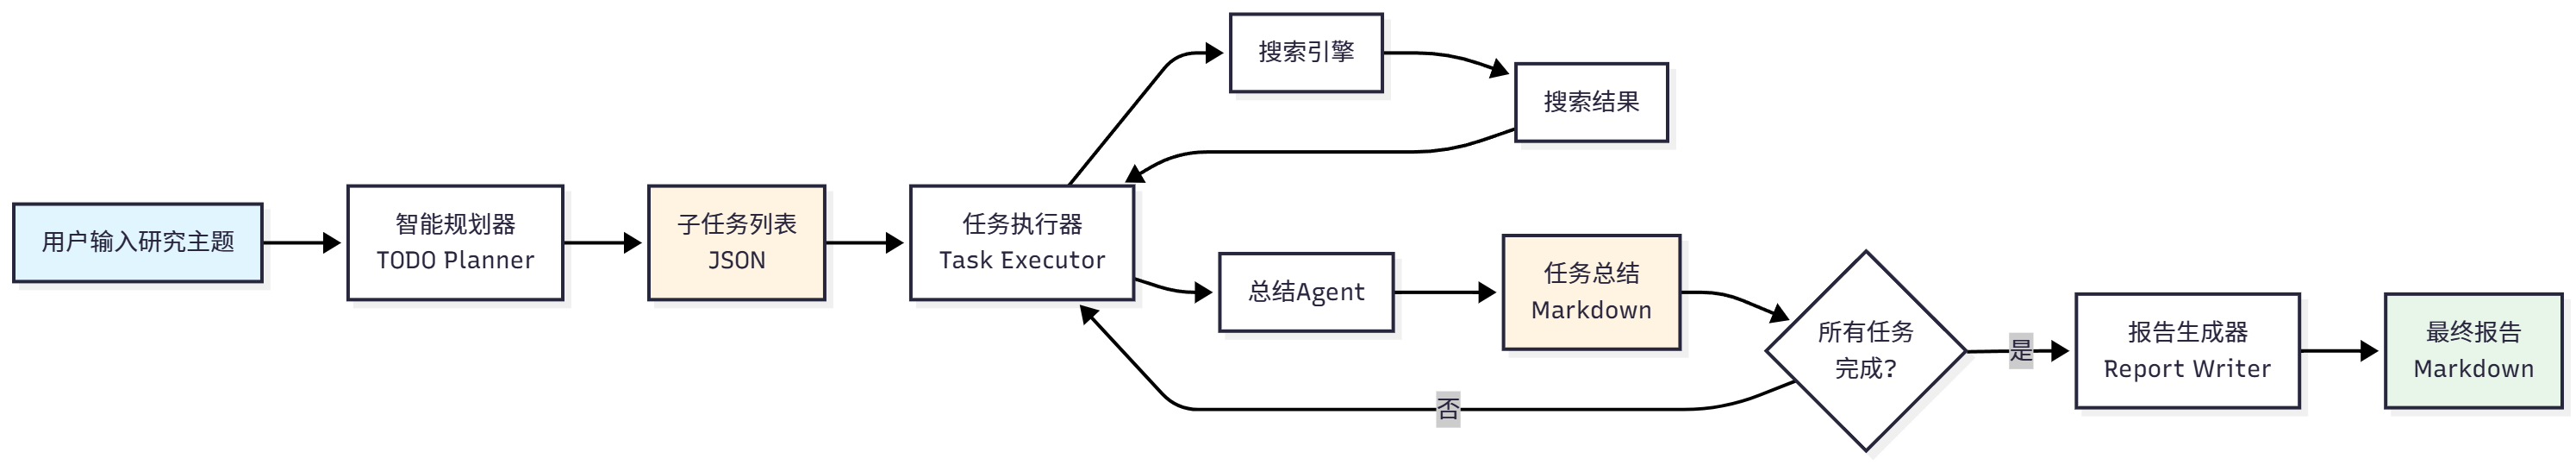
Figure 14.5 TODO-Driven Research Process
The entire process is linear, but each stage has clear inputs and outputs. This design makes the system easy to understand and debug.
14.2.2 Three-Stage Research Process
The TODO-driven research process is divided into three stages: Planning, Execution, and Reporting. Each stage has a dedicated Agent responsible for it.
(1) Stage 1: Planning
The goal of the planning stage is to decompose the research topic into 3-5 subtasks. The system receives the research topic and current date as input, and outputs a JSON-format list of subtasks. Each subtask contains three fields: title (task title), intent (research intent), and query (search query).
The research planning Agent adopts different decomposition strategies based on topic characteristics, usually starting with basic concepts, then understanding technical status, practical applications, and development trends, and conducting comparative analysis when necessary. For example, for "What kind of organization is Datawhale?", the planning Agent might generate the following subtasks:
[
  {
    "title": "Basic information about Datawhale",
    "intent": "Understand Datawhale's organizational positioning, founding time, development history",
    "query": "Datawhale organization introduction history 2024"
  },
  {
    "title": "Main projects of Datawhale",
    "intent": "Understand Datawhale's core open source projects and tutorials",
    "query": "Datawhale projects tutorials open source 2024"
  },
  ...
]
A good plan should be comprehensive, logically clear, have precise queries, and an appropriate number of items.
(2) Stage 2: Execution
The execution stage executes each subtask one by one, searching and summarizing relevant materials. The system receives the subtask list and search engine configuration as input, and outputs a summary (Markdown format) and source citation list for each subtask. The execution process is as follows:
For each subtask, the executor will:
Search for materials: Use the configured search engine to execute the search
pythonsearch_results = search_tool.run({ "input": task.query, "backend": "tavily", "mode": "structured", "max_results": 5 })Get search results: Extract title, URL, snippet
json{ "results": [ { "title": "What is a Multimodal Model?", "url": "https://example.com/multimodal-model", "snippet": "A multimodal model is an AI model that can process multiple types of data..." }, ... ] }Call summarization Agent: Summarize search results
pythonsummary = summarizer_agent.run( task=task, search_results=search_results )Record summary and sources: Save to NoteTool
pythonnote_tool.run({ "action": "create", "title": task.title, "content": f"## {task.title}\n\n{summary}\n\n## Sources\n{sources}", "tags": ["research", "summary"] })
The task summarization Agent will extract core viewpoints from each search result, merge similar information, retain important numbers, dates, names and other key data, and add source citations for each viewpoint. For example, for the search results of "Basic information about Datawhale", the summarization Agent might generate:
## Basic Information about Datawhale

Datawhale is an open source organization focused on data science and AI, founded in 2018[1]. The organization's core mission is "for the learner, grow together with learners", committed to building a pure learning community[2].

**Core Positioning:**

1. **Open Source Education Platform**: Provides high-quality AI and data science learning resources[1]
2. **Learner Community**: Gathers tens of thousands of AI learners and practitioners[3]
3. **Knowledge Sharing**: Advocates open source spirit, all content is completely free and open[2]

**Development History:**

- **2018**: Datawhale was founded, released first open source tutorial[1]
- **2020**: Became one of the leading AI learning communities in China[3]
- **2024**: Released 50+ open source projects, impacting 100,000+ learners[4]

## Sources

[1] https://github.com/datawhalechina
[2] https://datawhale.club/about
[3] https://www.zhihu.com/org/datawhale
[4] https://datawhale.cn
During execution, the system will push progress information to the front-end in real-time:
{
  "type": "status",
  "message": "Searching: Basic information about Datawhale"
}{
"type": "status",
"message": "Summarizing search results..."
}{
"type": "task",
"task": {
"id": 1,
"title": "Basic information about Datawhale",
"status": "completed"
}
}(3) Stage 3: Reporting
The goal of the reporting stage is to integrate the summaries of all subtasks and generate the final report. The system receives the summaries of all subtasks and the research topic as input, and outputs the final report in Markdown format. The report contains five parts: title, overview, detailed analysis of each subtask, summary, and references. For example, for "What kind of organization is Datawhale?", the final report might be:
# What Kind of Organization is Datawhale?

## Overview

This report systematically researched the open source organization Datawhale, covering four aspects: basic information, main projects, community culture, and influence.

## 1. Basic Information about Datawhale

Datawhale is an open source organization focused on data science and AI, founded in 2018...

(Insert summary of subtask 1 here)

## 2. Main Projects of Datawhale

Datawhale has released multiple high-quality open source tutorials, including Hello-Agents, Joyful-Pandas, etc...

(Insert summary of subtask 2 here)
...
## Summary

Through this research, we learned about Datawhale's organizational positioning, core projects, community culture, and social contributions. Datawhale is a pure learning community that has made important contributions to AI education.

## References

[1] https://github.com/datawhalechina
[2] https://datawhale.club/about
...
The report generation Agent will organize content in the logical order of subtasks, add a brief overview at the beginning, merge duplicate information, unify Markdown format, and organize all source citations into the references section.