How reasoning works
Reasoning models introduce reasoning tokens in addition to input and output tokens. The models use these reasoning tokens to "think," breaking down the prompt and considering multiple approaches to generating a response. Our reasoning models like gpt-5.5 and gpt-5.4 support interleaved thinking, where the model is able to generate visible output tokens before and in between thinking, and is able to think in between tool calls.
For models released before GPT-5.6, the default behavior in a multi-step conversation is to carry over input and output tokens from each step without rendering reasoning from earlier turns into the next sample. GPT-5.6 models instead default to rendering available reasoning from earlier turns. Use reasoning.context to select either behavior on supported models.
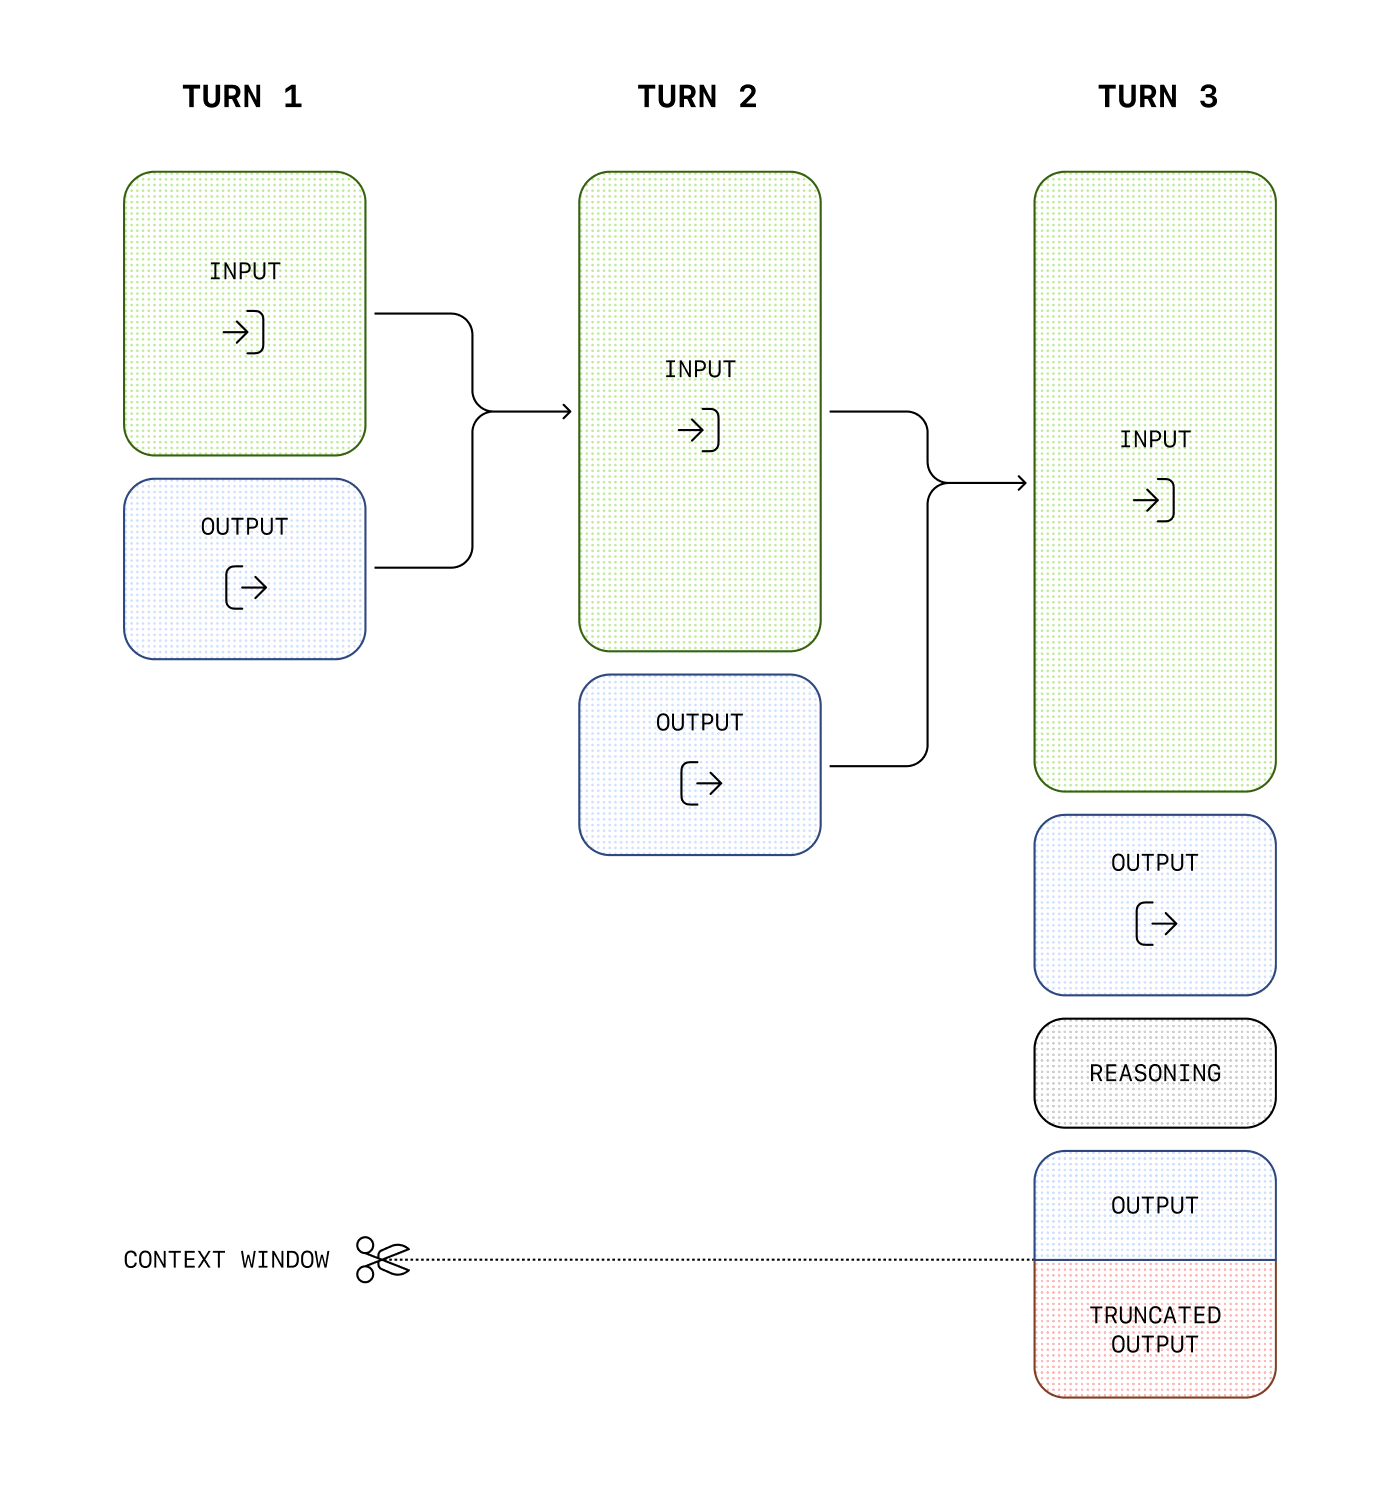
While reasoning tokens are not visible via the API, they still occupy space in the model's context window and are billed as output tokens.