# Reasoning models
> For the complete documentation index, see [llms.txt](/llms.txt). Markdown versions of documentation pages are available by appending `.md` to the page URL.
**Reasoning models** use internal reasoning tokens before producing a response. This helps the model plan, use tools effectively, inspect alternatives, recover from ambiguity, and solve harder multi-step tasks. Reasoning models work especially well for complex problem solving, coding, scientific reasoning, and multi-step agentic workflows. They're also the best models for [Codex CLI](https://github.com/openai/codex), our lightweight coding agent.
Start with `gpt-6-astra` for most reasoning workloads. For lower cost, consider [`gpt-5.6-terra`](https://developers.openai.com/api/docs/models/gpt-5.6-terra), or [`gpt-5.6-luna`](https://developers.openai.com/api/docs/models/gpt-5.6-luna) for the lowest cost and latency. If you're using a GPT-5.6 model, see [reasoning mode](#reasoning-mode) for its `pro` option.
**Reasoning models work better with the [Responses
API](https://developers.openai.com/api/docs/guides/migrate-to-responses)**. While the Chat Completions API
is still supported, you'll get improved model intelligence and performance by
using Responses.
## Get started with reasoning
Call the [Responses API](https://developers.openai.com/api/reference/resources/responses/methods/create) and specify your reasoning model and reasoning effort:
Using a reasoning model in the Responses API
```javascript
import OpenAI from "openai";
const openai = new OpenAI();
const prompt = `
Write a bash script that takes a matrix represented as a string with
format '[1,2],[3,4],[5,6]' and prints the transpose in the same format.
`;
const response = await openai.responses.create({
model: "gpt-6-astra",
reasoning: { effort: "low" },
input: [
{
role: "user",
content: prompt,
},
],
});
console.log(response.output_text);
```
```python
from openai import OpenAI
client = OpenAI()
prompt = """
Write a bash script that takes a matrix represented as a string with
format '[1,2],[3,4],[5,6]' and prints the transpose in the same format.
"""
response = client.responses.create(
model="gpt-6-astra",
reasoning={"effort": "low"},
input=[{"role": "user", "content": prompt}],
)
print(response.output_text)
```
```go
package main
import (
"context"
"fmt"
"github.com/openai/openai-go/v3"
"github.com/openai/openai-go/v3/responses"
)
func main() {
client := openai.NewClient()
prompt := `Write a bash script that takes a matrix represented as a string with
format '[1,2],[3,4],[5,6]' and prints the transpose in the same format.`
response, err := client.Responses.New(context.Background(), responses.ResponseNewParams{
Model: "gpt-6-astra",
Reasoning: responses.ReasoningParam{
Effort: responses.ReasoningEffortLow,
},
Input: responses.ResponseNewParamsInputUnion{
OfString: openai.String(prompt),
},
})
if err != nil {
panic(err)
}
fmt.Println(response.OutputText())
}
```
```java
import com.openai.client.OpenAIClient;
import com.openai.client.okhttp.OpenAIOkHttpClient;
import com.openai.models.Reasoning;
import com.openai.models.ReasoningEffort;
import com.openai.models.responses.ResponseCreateParams;
String prompt =
"""
Write a bash script that takes a matrix represented as a string with format
'[1,2],[3,4],[5,6]' and prints the transpose in the same format.
"""
.strip();
ResponseCreateParams params =
ResponseCreateParams.builder()
.model("gpt-6-astra")
.input(prompt)
.reasoning(Reasoning.builder().effort(ReasoningEffort.LOW).build())
.build();
client.responses().create(params).output().stream()
.flatMap(item -> item.message().stream())
.flatMap(message -> message.content().stream())
.flatMap(content -> content.outputText().stream())
.forEach(text -> System.out.println(text.text()));
```
```csharp
using OpenAI.Responses;
#pragma warning disable OPENAI001
string key = Environment.GetEnvironmentVariable("OPENAI_API_KEY")!;
ResponsesClient client = new(key);
string prompt =
"""
Write a bash script that takes a matrix represented as a string with format
'[1,2],[3,4],[5,6]' and prints the transpose in the same format.
""";
CreateResponseOptions options = new()
{
Model = "gpt-6-astra",
ReasoningOptions = new ResponseReasoningOptions
{
ReasoningEffortLevel = ResponseReasoningEffortLevel.Low,
},
};
options.InputItems.Add(ResponseItem.CreateUserMessageItem(prompt));
ResponseResult response = await client.CreateResponseAsync(options);
Console.WriteLine(response.GetOutputText());
```
```ruby
require "openai"
client = OpenAI::Client.new
prompt = <<~PROMPT
Write a bash script that takes a matrix represented as a string with format
'[1,2],[3,4],[5,6]' and prints the transpose in the same format.
PROMPT
response = client.responses.create(
model: "gpt-6-astra",
reasoning: {effort: :low},
input: prompt
)
puts(response.output_text)
```
```bash
curl https://api.openai.com/v1/responses \
-H "Content-Type: application/json" \
-H "Authorization: Bearer $OPENAI_API_KEY" \
-d '{
"model": "gpt-6-astra",
"reasoning": {"effort": "low"},
"input": [
{
"role": "user",
"content": "Write a bash script that takes a matrix represented as a string with format \"[1,2],[3,4],[5,6]\" and prints the transpose in the same format."
}
]
}'
```
## Reasoning effort
The `reasoning.effort` parameter guides the model on how much to think when performing a task.
Supported values are model-dependent and can include `none`, `minimal`, `low`, `medium`, `high`, `xhigh`, and `max`. Lower effort favors speed and lower token usage, while at higher effort the model thinks more completely to provide higher quality responses. The models also reason adaptively across reasoning efforts, using fewer tokens for simpler tasks and thinking harder for complex tasks.
[GPT-6 Astra](https://developers.openai.com/api/docs/models/gpt-6-astra) does not support `none` reasoning
effort. Setting `reasoning.effort` (Responses) or `reasoning_effort` (Chat
Completions) to `none` returns HTTP 400.
Use the [Responses API](https://developers.openai.com/api/docs/guides/migrate-to-responses) for function
calling. Chat Completions does not support function calling with GPT-6 Astra.
Defaults are also model-dependent rather than universal. `gpt-5.5` defaults to `medium` reasoning effort. This is the best starting point for `gpt-5.5`’s full balance of quality, reliability and performance.
| Effort | Best for |
| -------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `none` | Latency-critical tasks that do not benefit from any reasoning or multi-chained tool calls. For latency-sensitive use cases with `gpt-5.5`, we recommend trying `low` to begin with and then moving to `none` if required.
Common use cases include voice, fast information retrieval, and classification. |
| `low` | Efficient reasoning with a modest latency increase. Ideal for use cases requiring tool-use, planning, search, or multi-step decision making, while optimizing for speed and cost.
Common use cases include data analysis, drafting, execution-oriented coding, and customer support / chat assistant workflows. |
| `medium` | When quality and reliability matter, and the task involves planning, complex reasoning, and judgement. Default configuration for most workloads, and a well-balanced point on the pareto curve of latency, performance and cost.
Common use cases include agentic coding, research, working with spreadsheets & slides, and delegating long-horizon work. |
| `high` | Hard reasoning, complex debugging, deep planning, and high-value tasks where quality and intelligence matters more than latency. Recommended for complex workflows and agentic tasks.
Common use cases include agentic coding, long-horizon research, and knowledge work. Depending on the complexity of the task, evaluate both `medium` and `high`. |
| `xhigh` | Deep research, asynchronous workflows and agentic tasks that require long runs. Only use when your evals show a clear benefit that justifies the extra latency and cost.
Common use cases include security and code review, enterprise productivity, deeper research tasks, and challenging coding workflows. |
| `max` | Maximum reasoning for your most complex tasks. If you are currently using `xhigh`, evaluate if `max` results in stronger performance |
For faster time to first visible token in latency-sensitive applications, ask the model to generate a short preamble before continuing with deeper reasoning.
Some models support only a subset of these values, so check the relevant [model page](https://developers.openai.com/api/docs/models) before choosing a setting.
## Reasoning mode
GPT-5.6 models support `standard` and `pro` reasoning modes in the Responses API. `standard` is the default. Set `reasoning.mode` to `pro` for difficult tasks that need more model work and can tolerate higher latency and token usage.
Reasoning mode and reasoning effort are independent. Mode selects standard or pro execution, while `reasoning.effort` controls how much reasoning the model applies within that mode. If you omit `reasoning.effort`, GPT-5.6 defaults to `medium` in both modes.
Using pro reasoning mode
```bash
curl https://api.openai.com/v1/responses \
-H "Content-Type: application/json" \
-H "Authorization: Bearer $OPENAI_API_KEY" \
-d '{
"model": "gpt-5.6",
"reasoning": {
"mode": "pro",
"effort": "medium"
},
"input": "Review this database migration plan and identify potential failure modes."
}'
```
Pro mode aggregates the model work performed to produce the final answer and bills those tokens at the selected model's standard [token rates](https://developers.openai.com/api/docs/pricing). Pro mode performs more model work than standard mode, increasing token usage and cost. Existing Pro model IDs keep their current behavior and pricing.
## How reasoning works
Reasoning models introduce **reasoning tokens** in addition to input and output tokens. The models use these reasoning tokens to "think," breaking down the prompt and considering multiple approaches to generating a response. Our reasoning models like `gpt-5.5` and `gpt-5.4` support interleaved thinking, where the model is able to generate visible output tokens before and in between thinking, and is able to think in between tool calls.
For models released before GPT-5.6, the default behavior in a multi-step conversation is to carry over input and output tokens from each step without rendering reasoning from earlier turns into the next sample. GPT-5.6 models instead default to rendering available reasoning from earlier turns. Use `reasoning.context` to select either behavior on supported models.
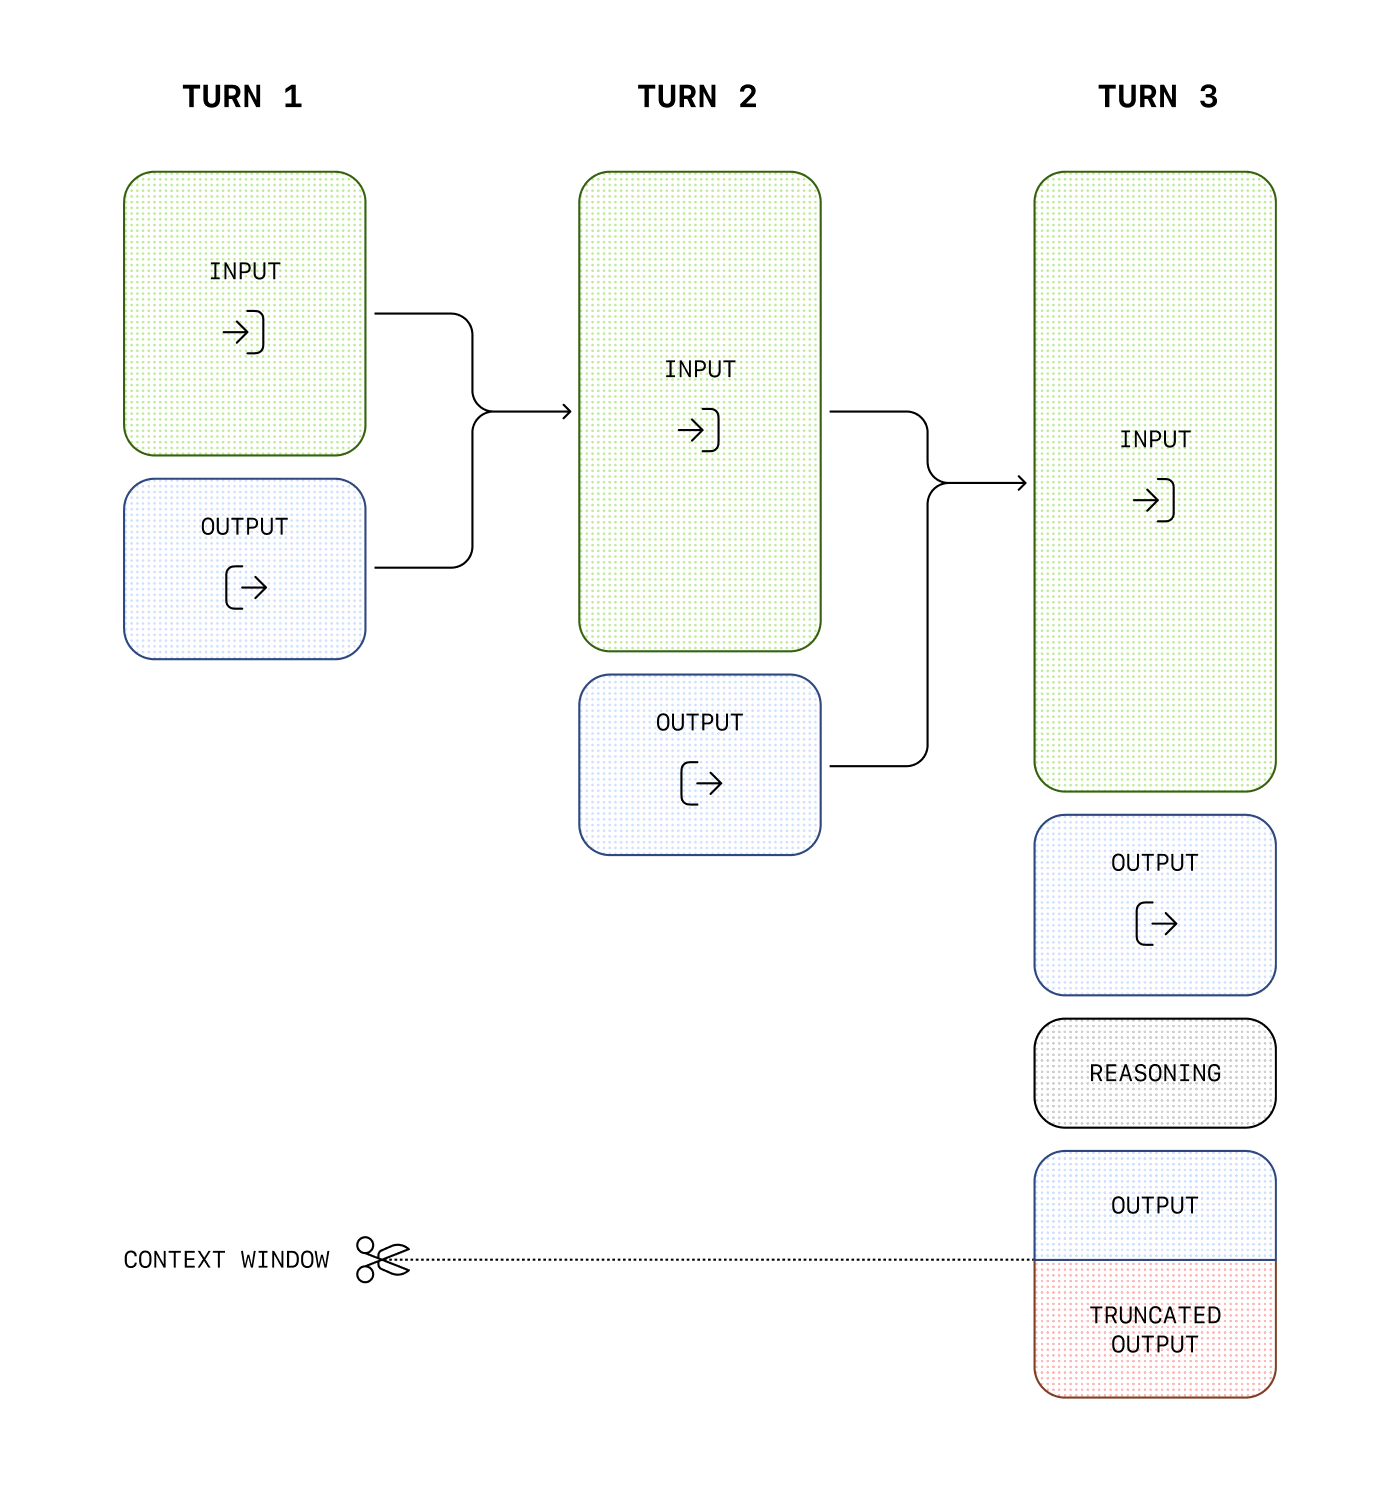
While reasoning tokens are not visible via the API, they still occupy space in
the model's context window and are billed as [output
tokens](https://openai.com/api/pricing).
## Controlling costs
To manage costs with reasoning models, you can limit the total number of tokens the
model generates, including reasoning tokens, visible output tokens, and non-visible
formatting tokens, by using the
[`max_output_tokens`](https://developers.openai.com/api/reference/resources/responses/methods/create#responses-create-max_output_tokens)
parameter. See [output token counts](https://developers.openai.com/api/docs/guides/token-counting#understand-output-token-counts) for details about how generated tokens are reflected in usage and output limits.
### Managing the context window
It's important to ensure there's enough space in the context window for reasoning tokens when creating responses. Depending on the problem's complexity, the models may generate anywhere from a few hundred to tens of thousands of reasoning tokens. The exact number of reasoning tokens used is visible in the [usage object of the response object](https://developers.openai.com/api/reference/resources/responses), under `output_tokens_details`:
```json
{
"usage": {
"input_tokens": 75,
"input_tokens_details": {
"cached_tokens": 0
},
"output_tokens": 1186,
"output_tokens_details": {
"reasoning_tokens": 1024
},
"total_tokens": 1261
}
}
```
Context window lengths are found on the [model reference page](https://developers.openai.com/api/docs/models), and will differ across model snapshots.
### Allocating space for reasoning
If the generated tokens reach the context window limit or the `max_output_tokens` value you've set, you'll receive a response with a `status` of `incomplete` and `incomplete_details` with `reason` set to `max_output_tokens`. This might occur before any visible output tokens are produced, meaning you could incur costs for input and reasoning tokens without receiving a visible response.
To prevent this, ensure there's sufficient space in the context window or adjust the `max_output_tokens` value to a higher number. OpenAI recommends reserving at least 25,000 tokens for reasoning and outputs when you start experimenting with these models. As you become familiar with the number of reasoning tokens your prompts require, you can adjust this buffer accordingly.
Handling incomplete responses
```javascript
import OpenAI from "openai";
const openai = new OpenAI();
const prompt = `
Write a bash script that takes a matrix represented as a string with
format '[1,2],[3,4],[5,6]' and prints the transpose in the same format.
`;
const response = await openai.responses.create({
model: "gpt-6-astra",
reasoning: { effort: "medium" },
input: [
{
role: "user",
content: prompt,
},
],
max_output_tokens: 300,
});
if (
response.status === "incomplete" &&
response.incomplete_details.reason === "max_output_tokens"
) {
console.log("Ran out of tokens");
if (response.output_text?.length > 0) {
console.log("Partial output:", response.output_text);
} else {
console.log("Ran out of tokens during reasoning");
}
}
```
```python
from openai import OpenAI
client = OpenAI()
prompt = """
Write a bash script that takes a matrix represented as a string with
format '[1,2],[3,4],[5,6]' and prints the transpose in the same format.
"""
response = client.responses.create(
model="gpt-6-astra",
reasoning={"effort": "medium"},
input=[{"role": "user", "content": prompt}],
max_output_tokens=300,
)
if (
response.status == "incomplete"
and response.incomplete_details.reason == "max_output_tokens"
):
print("Ran out of tokens")
if response.output_text:
print("Partial output:", response.output_text)
else:
print("Ran out of tokens during reasoning")
```
```go
package main
import (
"context"
"fmt"
"github.com/openai/openai-go/v3"
"github.com/openai/openai-go/v3/responses"
)
func main() {
client := openai.NewClient()
prompt := `Write a bash script that takes a matrix represented as a string with
format '[1,2],[3,4],[5,6]' and prints the transpose in the same format.`
response, err := client.Responses.New(context.Background(), responses.ResponseNewParams{
Model: "gpt-6-astra",
MaxOutputTokens: openai.Int(300),
Reasoning: responses.ReasoningParam{
Effort: responses.ReasoningEffortMedium,
},
Input: responses.ResponseNewParamsInputUnion{
OfString: openai.String(prompt),
},
})
if err != nil {
panic(err)
}
if response.Status == responses.ResponseStatusIncomplete {
fmt.Println("Ran out of tokens")
if text := response.OutputText(); text != "" {
fmt.Println("Partial output:", text)
}
}
}
```
```java
import com.openai.client.OpenAIClient;
import com.openai.client.okhttp.OpenAIOkHttpClient;
import com.openai.models.Reasoning;
import com.openai.models.ReasoningEffort;
import com.openai.models.responses.Response;
import com.openai.models.responses.ResponseCreateParams;
import com.openai.models.responses.ResponseStatus;
ResponseCreateParams params =
ResponseCreateParams.builder()
.model("gpt-6-astra")
.input(
"Write a bash script that takes a matrix represented as a string with format "
+ "'[1,2],[3,4],[5,6]' and prints the transpose in the same format.")
.maxOutputTokens(300)
.reasoning(Reasoning.builder().effort(ReasoningEffort.MEDIUM).build())
.build();
var response = client.responses().create(params);
if (response.status().filter(ResponseStatus.INCOMPLETE::equals).isPresent()
&& response
.incompleteDetails()
.flatMap(Response.IncompleteDetails::reason)
.filter(Response.IncompleteDetails.Reason.MAX_OUTPUT_TOKENS::equals)
.isPresent()) {
System.out.println("Ran out of tokens");
response.output().stream()
.flatMap(item -> item.message().stream())
.flatMap(message -> message.content().stream())
.flatMap(content -> content.outputText().stream())
.forEach(text -> System.out.println("Partial output: " + text.text()));
}
```
```csharp
using OpenAI.Responses;
#pragma warning disable OPENAI001
string key = Environment.GetEnvironmentVariable("OPENAI_API_KEY")!;
ResponsesClient client = new(key);
CreateResponseOptions options = new()
{
Model = "gpt-6-astra",
MaxOutputTokenCount = 300,
ReasoningOptions = new ResponseReasoningOptions
{
ReasoningEffortLevel = ResponseReasoningEffortLevel.Medium,
},
};
options.InputItems.Add(
ResponseItem.CreateUserMessageItem("Write a bash script that transposes a matrix.")
);
ResponseResult response = await client.CreateResponseAsync(options);
if (
response.Status == ResponseStatus.Incomplete
&& response.IncompleteStatusDetails?.Reason == ResponseIncompleteStatusReason.MaxOutputTokens
)
{
Console.WriteLine("The response ended before all output tokens were generated.");
string partialOutput = response.GetOutputText();
Console.WriteLine(
string.IsNullOrWhiteSpace(partialOutput)
? "Ran out of tokens during reasoning."
: $"Partial output: {partialOutput}"
);
}
else if (
response.Status == ResponseStatus.Incomplete
&& response.IncompleteStatusDetails?.Reason == ResponseIncompleteStatusReason.ContentFilter
)
{
Console.WriteLine("The response was interrupted by the content filter.");
}
else if (response.Status == ResponseStatus.Completed)
{
Console.WriteLine(response.GetOutputText());
}
else
{
throw new InvalidOperationException($"The response ended with status: {response.Status}");
}
```
```ruby
require "openai"
client = OpenAI::Client.new
prompt = <<~PROMPT
Write a bash script that takes a matrix represented as a string with format
'[1,2],[3,4],[5,6]' and prints the transpose in the same format.
PROMPT
response = client.responses.create(
model: "gpt-6-astra",
max_output_tokens: 300,
reasoning: {effort: :medium},
input: prompt
)
if response.status == OpenAI::Responses::ResponseStatus::INCOMPLETE
puts("Ran out of tokens")
puts("Partial output: #{response.output_text}") unless response.output_text.empty?
end
```
## Preserve reasoning across calls
Conversation state and reasoning state serve different purposes. Passing messages across calls gives the model the visible conversation history. On supported models, persisted reasoning also lets the model render compatible reasoning items from earlier turns into its next context.
Persisted reasoning provides continuity; it does not expose the model's raw reasoning. The reasoning items remain opaque, and the API does not return their reasoning text. Set `reasoning.context` to control which available reasoning items the model can use:
The [GPT-5.6 model family](https://developers.openai.com/api/docs/guides/latest-model?model=gpt-5.6)
supports
`all_turns` and uses it by default. Earlier models default to
`current_turn`. Omit `reasoning.context` or set it to
`auto` to use the selected model's default.
| Value | Behavior |
| -------------- | ------------------------------------------------------------------------------------------------------------------------- |
| `auto` | Uses the selected model's default. Omitting `reasoning.context` has the same effect as `auto`. |
| `current_turn` | Makes reasoning from the active turn available, but does not render reasoning from earlier turns into the next sample. |
| `all_turns` | Renders available, compatible reasoning items from earlier turns into the next sample. GPT-5.6 models support this value. |
The response's `reasoning.context` field contains the effective mode, either `current_turn` or `all_turns`. Check this field on each response to confirm which mode the model used. The setting does not create reasoning items that are not already available.
`all_turns` has an effect only when the request has access to earlier response items. Use `previous_response_id`, attach the response to a conversation, or manually replay the complete response history. On the first request, `current_turn` and `all_turns` behave the same because no earlier reasoning exists.
Persisted reasoning can be reused only within the same model family. For example, `gpt-5.6-sol`, `gpt-5.6-terra`, and `gpt-5.6-luna` can reuse each other's reasoning, but reasoning does not carry between the GPT-5.6 and GPT-5.5 families.
When you switch model families, the API omits incompatible reasoning from the model's context, even when `reasoning.context` is `all_turns`.
### Continue reasoning with stored responses
Use `previous_response_id` for the shortest stateful integration:
Preserve reasoning with a previous response
```javascript
import OpenAI from "openai";
const client = new OpenAI();
const first = await client.responses.create({
model: "gpt-5.6",
input: "Inspect this repository and identify the likely bug.",
reasoning: { context: "current_turn" },
});
const second = await client.responses.create({
model: "gpt-5.6",
previous_response_id: first.id,
input: "Now patch the bug and explain the change.",
reasoning: { context: "all_turns" },
});
console.log(second.output_text);
```
```python
from openai import OpenAI
client = OpenAI()
model = "gpt-5.6"
first = client.responses.create(
model=model,
input="Inspect this repository and identify the likely bug.",
reasoning={"context": "current_turn"},
)
second = client.responses.create(
model=model,
previous_response_id=first.id,
input="Now patch the bug and explain the change.",
reasoning={"context": "all_turns"},
)
print(second.output_text)
```
```go
package main
import (
"context"
"fmt"
"github.com/openai/openai-go/v3"
"github.com/openai/openai-go/v3/responses"
)
func main() {
client := openai.NewClient()
model := "gpt-5.6"
first, err := client.Responses.New(context.Background(), responses.ResponseNewParams{
Model: model,
Input: responses.ResponseNewParamsInputUnion{
OfString: openai.String("Inspect this repository and identify the likely bug."),
},
Reasoning: responses.ReasoningParam{
Context: responses.ReasoningContextCurrentTurn,
},
})
if err != nil {
panic(err)
}
second, err := client.Responses.New(context.Background(), responses.ResponseNewParams{
Model: model,
PreviousResponseID: openai.String(first.ID),
Input: responses.ResponseNewParamsInputUnion{
OfString: openai.String("Now patch the bug and explain the change."),
},
Reasoning: responses.ReasoningParam{
Context: responses.ReasoningContextAllTurns,
},
})
if err != nil {
panic(err)
}
fmt.Println(second.OutputText())
}
```
```java
import com.openai.client.OpenAIClient;
import com.openai.client.okhttp.OpenAIOkHttpClient;
import com.openai.core.JsonValue;
import com.openai.models.Reasoning;
import com.openai.models.responses.ResponseCreateParams;
var first =
client
.responses()
.create(
ResponseCreateParams.builder()
.model("gpt-5.6")
.input("Inspect this repository and identify the likely bug.")
.reasoning(
Reasoning.builder()
.putAdditionalProperty("context", JsonValue.from("current_turn"))
.build())
.build());
var second =
client
.responses()
.create(
ResponseCreateParams.builder()
.model("gpt-5.6")
.input("Now patch the bug and explain the change.")
.previousResponseId(first.id())
.reasoning(
Reasoning.builder()
.putAdditionalProperty("context", JsonValue.from("all_turns"))
.build())
.build());
second.output().stream()
.flatMap(item -> item.message().stream())
.flatMap(message -> message.content().stream())
.flatMap(content -> content.outputText().stream())
.forEach(text -> System.out.println(text.text()));
```
```ruby
require "openai"
client = OpenAI::Client.new
first = client.responses.create(
model: "gpt-5.6",
input: "Inspect this repository and identify the likely bug.",
reasoning: {context: :current_turn}
)
second = client.responses.create(
model: "gpt-5.6",
previous_response_id: first.id,
input: "Now patch the bug and explain the change.",
reasoning: {context: :all_turns}
)
puts(second.output_text)
```
Use `current_turn` when replaying older response items that the model no longer needs. Those reasoning items can remain in the API payload for continuity, but the service does not render them into the new sample. This can reduce the rendered context for long-running workflows.
### Preserve reasoning without stored responses
When you create a response in stateless mode, reasoning items in the response's `output` array include an `encrypted_content` property by default. Stateless mode applies when `store` is `false` or when your organization uses Zero Data Retention (ZDR). The API still accepts the legacy `reasoning.encrypted_content` value in `include` for compatibility, but doesn't require it.
The following request returns encrypted reasoning content without specifying `include`:
```bash
curl https://api.openai.com/v1/responses \
-H "Content-Type: application/json" \
-H "Authorization: Bearer $OPENAI_API_KEY" \
-d '{
"model": "gpt-6-astra",
"store": false,
"reasoning": {"effort": "medium"},
"input": "What is the weather like today?",
"tools": [ ... function config here ... ]
}'
```
Reasoning items in the `output` array will include an `encrypted_content` property containing encrypted reasoning tokens that you can pass to future calls.
To use `all_turns` with `store: false`, preserve every output item, append the next user message, and replay the complete history:
Preserve reasoning without storing responses
```javascript
import OpenAI from "openai";
import { toResponseInputItems } from "openai/lib/responses/ResponseInputItems";
const client = new OpenAI();
/** @type {OpenAI.Responses.ResponseInput} */
const history = [
{
role: "user",
content: "Inspect this repository and identify the likely bug.",
},
];
const first = await client.responses.create({
model: "gpt-5.6",
store: false,
input: history,
reasoning: { context: "current_turn" },
});
// Keep replayable output, including encrypted reasoning and assistant phase.
history.push(...toResponseInputItems(first.output));
history.push({
role: "user",
content: "Now patch the bug and explain the change.",
});
const second = await client.responses.create({
model: "gpt-5.6",
store: false,
input: history,
reasoning: { context: "all_turns" },
});
console.log(second.output_text);
```
```python
from openai import OpenAI
client = OpenAI()
model = "gpt-5.6"
history = [
{
"role": "user",
"content": "Inspect this repository and identify the likely bug.",
}
]
first = client.responses.create(
model=model,
store=False,
input=history,
reasoning={"context": "current_turn"},
)
# Keep every output item, including encrypted reasoning and assistant phase.
history.extend(item.model_dump() for item in first.output)
history.append(
{
"role": "user",
"content": "Now patch the bug and explain the change.",
}
)
second = client.responses.create(
model=model,
store=False,
input=history,
reasoning={"context": "all_turns"},
)
print(second.output_text)
```
```go
package main
import (
"context"
"encoding/json"
"fmt"
"github.com/openai/openai-go/v3"
"github.com/openai/openai-go/v3/responses"
"github.com/openai/openai-go/v3/shared"
)
func main() {
client := openai.NewClient()
history := []responses.ResponseInputItemUnionParam{
responses.ResponseInputItemParamOfMessage("Inspect this repository and identify the likely bug.", responses.EasyInputMessageRoleUser),
}
first, err := client.Responses.New(context.Background(), responses.ResponseNewParams{
Model: "gpt-5.6",
Store: openai.Bool(false),
Input: responses.ResponseNewParamsInputUnion{OfInputItemList: history},
Reasoning: shared.ReasoningParam{Context: shared.ReasoningContextCurrentTurn},
})
if err != nil {
panic(err)
}
history = append(history, outputAsInput(first.Output)...)
history = append(history, responses.ResponseInputItemParamOfMessage(
"Now patch the bug and explain the change.",
responses.EasyInputMessageRoleUser,
))
second, err := client.Responses.New(context.Background(), responses.ResponseNewParams{
Model: "gpt-5.6",
Store: openai.Bool(false),
Input: responses.ResponseNewParamsInputUnion{OfInputItemList: history},
Reasoning: shared.ReasoningParam{Context: shared.ReasoningContextAllTurns},
})
if err != nil {
panic(err)
}
fmt.Println(second.OutputText())
}
func outputAsInput(output []responses.ResponseOutputItemUnion) []responses.ResponseInputItemUnionParam {
input := make([]responses.ResponseInputItemUnionParam, 0, len(output))
for _, item := range output {
var converted responses.ResponseInputItemUnion
if err := json.Unmarshal([]byte(item.RawJSON()), &converted); err != nil {
panic(err)
}
input = append(input, converted.ToParam())
}
return input
}
```
```java
import com.openai.client.OpenAIClient;
import com.openai.client.okhttp.OpenAIOkHttpClient;
import com.openai.core.JsonValue;
import com.openai.models.Reasoning;
import com.openai.models.responses.EasyInputMessage;
import com.openai.models.responses.ResponseCreateParams;
import com.openai.models.responses.ResponseInputItem;
import java.util.ArrayList;
var history = new ArrayList();
history.add(
ResponseInputItem.ofEasyInputMessage(
EasyInputMessage.builder()
.role(EasyInputMessage.Role.USER)
.content("Inspect this repository and identify the likely bug.")
.build()));
var first =
client
.responses()
.create(
ResponseCreateParams.builder()
.model("gpt-5.6")
.inputOfResponse(history)
.store(false)
.reasoning(
Reasoning.builder()
.putAdditionalProperty("context", JsonValue.from("current_turn"))
.build())
.build());
first.output().stream()
.map(item -> JsonValue.from(item).convert(ResponseInputItem.class))
.forEach(history::add);
history.add(
ResponseInputItem.ofEasyInputMessage(
EasyInputMessage.builder()
.role(EasyInputMessage.Role.USER)
.content("Now patch the bug and explain the change.")
.build()));
client
.responses()
.create(
ResponseCreateParams.builder()
.model("gpt-5.6")
.inputOfResponse(history)
.store(false)
.reasoning(
Reasoning.builder()
.putAdditionalProperty("context", JsonValue.from("all_turns"))
.build())
.build())
.output()
.stream()
.flatMap(item -> item.message().stream())
.flatMap(message -> message.content().stream())
.flatMap(content -> content.outputText().stream())
.forEach(text -> System.out.println(text.text()));
```
```ruby
require "openai"
client = OpenAI::Client.new
history = [
{role: :user, content: "Inspect this repository and identify the likely bug."}
]
first = client.responses.create(
model: "gpt-5.6",
store: false,
input: history,
reasoning: {context: :current_turn}
)
history.concat(first.output)
history << {role: :user, content: "Now patch the bug and explain the change."}
second = client.responses.create(
model: "gpt-5.6",
store: false,
input: history,
reasoning: {context: :all_turns}
)
puts(second.output_text)
```
### Keeping reasoning items in context
When doing [function calling](https://developers.openai.com/api/docs/guides/function-calling) with a reasoning model in the [Responses API](https://developers.openai.com/api/reference/resources/responses), we highly recommend you pass back any reasoning items returned with the last function call (in addition to the output of your function). If the model calls multiple functions consecutively, you should pass back all reasoning items, function call items, and function call output items, since the last `user` message. This allows the model to continue its reasoning process to produce better results in the most token-efficient manner.
The simplest way to do this is to pass in all reasoning items from a previous response into the next one. Our systems will smartly ignore any reasoning items that aren't relevant to your functions, and only retain those in context that are relevant. You can pass reasoning items from previous responses either using the `previous_response_id` parameter, or by manually passing in all the [output](https://developers.openai.com/api/reference/resources/responses#responses/object-output) items from a past response into the [input](https://developers.openai.com/api/reference/resources/responses/methods/create#responses-create-input) of a new one.
For advanced use cases where you might be truncating and optimizing parts of the context window before passing them on to the next response, just ensure all items between the last user message and your function call output are passed into the next response untouched. This will ensure that the model has all the context it needs.
Check out [this guide](https://developers.openai.com/api/docs/guides/conversation-state) to learn more about manual context management.
## Change reasoning mid-conversation
Use `configuration_update` to increase reasoning effort for difficult work or reduce it for routine follow-ups. Add the update between responses while leaving the request-level `reasoning.effort` unchanged. This preserves the original prompt prefix for [prompt caching](https://developers.openai.com/api/docs/guides/prompt-caching).
Configuration updates are supported only by GPT-6 Astra (`gpt-6-astra`) in
standard, single-agent mode. They change only reasoning effort.
Add the following item before the next user message in the `input` array of an HTTP Responses request or a WebSocket `response.create` request:
```json
{
"type": "configuration_update",
"reasoning": {
"effort": "high"
}
}
```
For example, if the conversation starts with request-level effort `low`, this update selects `high` for the next response and subsequent responses until another update overrides it.
Increase reasoning effort for a follow-up
```javascript
import OpenAI from "openai";
const client = new OpenAI();
const model = "gpt-6-astra";
const first = await client.responses.create({
model,
reasoning: { effort: "low" },
input: "Draft a database migration plan.",
});
const next = await client.responses.create({
model,
reasoning: { effort: "low" },
previous_response_id: first.id,
input: [
{ type: "configuration_update", reasoning: { effort: "high" } },
{
role: "user",
content: "Analyze the failure modes and propose rollback steps.",
},
],
});
console.log(next.output_text);
```
```python
from openai import OpenAI
client = OpenAI()
model = "gpt-6-astra"
response = client.responses.create(
model=model,
reasoning={"effort": "low"},
input="Draft a database migration plan.",
store=True,
)
print(response.output_text)
response = client.responses.create(
model=model,
previous_response_id=response.id,
reasoning={"effort": "low"},
input=[
{
"type": "configuration_update",
"reasoning": {"effort": "high"},
},
{
"role": "user",
"content": "Analyze the failure modes and propose rollback steps.",
},
],
store=True,
)
print(response.output_text)
```
```go
package main
import (
"context"
"fmt"
"github.com/openai/openai-go/v3"
"github.com/openai/openai-go/v3/responses"
"github.com/openai/openai-go/v3/shared"
)
func main() {
client := openai.NewClient()
ctx := context.Background()
first, err := client.Responses.New(ctx, responses.ResponseNewParams{
Store: openai.Bool(true),
Model: "gpt-6-astra",
Reasoning: shared.ReasoningParam{Effort: shared.ReasoningEffortLow},
Input: responses.ResponseNewParamsInputUnion{OfString: openai.String("Draft a database migration plan.")},
})
if err != nil {
panic(err)
}
fmt.Println(first.OutputText())
response, err := client.Responses.New(ctx, responses.ResponseNewParams{
Model: "gpt-6-astra",
PreviousResponseID: openai.String(first.ID),
// Keep the original request-level setting; the item updates the conversation.
Reasoning: shared.ReasoningParam{Effort: shared.ReasoningEffortLow},
Input: responses.ResponseNewParamsInputUnion{OfInputItemList: responses.ResponseInputParam{
{OfConfigurationUpdate: &responses.ResponseConfigurationUpdateItemParam{
Reasoning: responses.ResponseConfigurationUpdateItemParamReasoning{Effort: shared.ReasoningEffortHigh},
}},
responses.ResponseInputItemParamOfMessage("Analyze the failure modes and propose rollback steps.", responses.EasyInputMessageRoleUser),
}},
})
if err != nil {
panic(err)
}
fmt.Println(response.OutputText())
}
```
```java
import com.openai.models.Reasoning;
import com.openai.models.ReasoningEffort;
import com.openai.models.responses.EasyInputMessage;
import com.openai.models.responses.Response;
import com.openai.models.responses.ResponseConfigurationUpdateItemParam;
import com.openai.models.responses.ResponseCreateParams;
import com.openai.models.responses.ResponseInputItem;
import java.util.List;
Response first =
client
.responses()
.create(
ResponseCreateParams.builder()
.model("gpt-6-astra")
.store(true)
.reasoning(Reasoning.builder().effort(ReasoningEffort.LOW).build())
.input("Draft a database migration plan.")
.build());
Response response =
client
.responses()
.create(
ResponseCreateParams.builder()
.model("gpt-6-astra")
.previousResponseId(first.id())
// Keep the original request-level setting; the item updates the conversation.
.reasoning(Reasoning.builder().effort(ReasoningEffort.LOW).build())
.inputOfResponse(
List.of(
ResponseInputItem.ofConfigurationUpdate(
ResponseConfigurationUpdateItemParam.builder()
.reasoning(
ResponseConfigurationUpdateItemParam.Reasoning.builder()
.effort(ReasoningEffort.HIGH)
.build())
.build()),
ResponseInputItem.ofEasyInputMessage(
EasyInputMessage.builder()
.role(EasyInputMessage.Role.USER)
.content(
"Analyze the failure modes and propose rollback steps.")
.build())))
.build());
response.output().stream()
.flatMap(item -> item.message().stream())
.flatMap(message -> message.content().stream())
.flatMap(content -> content.outputText().stream())
.forEach(text -> System.out.println(text.text()));
```
```ruby
require "openai"
client = OpenAI::Client.new
first = client.responses.create(
model: "gpt-6-astra",
store: true,
reasoning: OpenAI::Models::Reasoning.new(effort: :low),
input: "Draft a database migration plan."
)
puts(first.output_text)
response = client.responses.create(
model: "gpt-6-astra",
previous_response_id: first.id,
# Keep the original request-level setting; the item updates the conversation.
reasoning: OpenAI::Models::Reasoning.new(effort: :low),
input: [
OpenAI::Models::Responses::ResponseConfigurationUpdateItemParam.new(
reasoning: OpenAI::Models::Responses::ResponseConfigurationUpdateItemParam::Reasoning.new(
effort: :high
)
),
OpenAI::Models::Responses::EasyInputMessage.new(
role: :user,
content: "Analyze the failure modes and propose rollback steps."
)
]
)
puts(response.output_text)
```
Preserve updates with `previous_response_id`, or replay them in their original positions when [managing conversation history manually](https://developers.openai.com/api/docs/guides/conversation-state#manually-manage-conversation-state). The response's `reasoning.effort` continues to report the request-level setting, not the effort selected by the update.
Do not place two `configuration_update` items directly next to each other in the conversation history; the API rejects adjacent updates.
Do not combine configuration updates with automatic compaction or automatic truncation. The standalone `/responses/compact` endpoint also rejects histories containing these updates.
You can still explicitly compact history by including a `compaction_trigger` item in a `/responses` request. After compaction, add a fresh `configuration_update` with the desired effort before the next user message.
Normal prompt caching requirements still apply. To send user instructions while a response is running, use [Mid-turn steering](https://developers.openai.com/api/docs/guides/steering).
## Reasoning summaries
While we don't expose the raw reasoning tokens emitted by the model, you can view a summary of the model's reasoning using the `summary` parameter. See our [model documentation](https://developers.openai.com/api/docs/models) to check which reasoning models support summaries.
Different models support different reasoning summary settings. For example, our computer use model supports the `concise` summarizer, while o4-mini supports `detailed`. To access the most detailed summarizer available for a model, set the value of this parameter to `auto`. `auto` will be equivalent to `detailed` for most reasoning models today, but there may be more granular settings in the future.
Reasoning summary output is part of the `summary` array in the `reasoning` [output item](https://developers.openai.com/api/reference/resources/responses#responses/object-output). This output will not be included unless you explicitly opt in to including reasoning summaries.
The example below shows how to make an API request that includes a reasoning summary.
Include a reasoning summary with the API response
```javascript
import OpenAI from "openai";
const openai = new OpenAI();
const response = await openai.responses.create({
model: "gpt-6-astra",
input: "What is the capital of France?",
reasoning: {
effort: "low",
summary: "auto",
},
});
console.log(response.output);
```
```python
from openai import OpenAI
client = OpenAI()
response = client.responses.create(
model="gpt-6-astra",
input="What is the capital of France?",
reasoning={"effort": "low", "summary": "auto"},
)
print(response.output)
```
```go
package main
import (
"context"
"fmt"
"github.com/openai/openai-go/v3"
"github.com/openai/openai-go/v3/responses"
)
func main() {
client := openai.NewClient()
response, err := client.Responses.New(context.Background(), responses.ResponseNewParams{
Model: "gpt-6-astra",
Input: responses.ResponseNewParamsInputUnion{
OfString: openai.String("What is the capital of France?"),
},
Reasoning: responses.ReasoningParam{
Effort: responses.ReasoningEffortLow,
Summary: responses.ReasoningSummaryAuto,
},
})
if err != nil {
panic(err)
}
fmt.Println(response.Output)
}
```
```java
import com.openai.client.OpenAIClient;
import com.openai.client.okhttp.OpenAIOkHttpClient;
import com.openai.models.Reasoning;
import com.openai.models.ReasoningEffort;
import com.openai.models.responses.ResponseCreateParams;
ResponseCreateParams params =
ResponseCreateParams.builder()
.model("gpt-6-astra")
.input("What is the capital of France?")
.reasoning(
Reasoning.builder()
.effort(ReasoningEffort.LOW)
.summary(Reasoning.Summary.AUTO)
.build())
.build();
client.responses().create(params).output().stream()
.flatMap(item -> item.reasoning().stream())
.flatMap(reasoning -> reasoning.summary().stream())
.forEach(summary -> System.out.println(summary.text()));
```
```csharp
using OpenAI.Responses;
#pragma warning disable OPENAI001
string key = Environment.GetEnvironmentVariable("OPENAI_API_KEY")!;
ResponsesClient client = new(key);
CreateResponseOptions options = new()
{
Model = "gpt-6-astra",
ReasoningOptions = new ResponseReasoningOptions
{
ReasoningEffortLevel = ResponseReasoningEffortLevel.Low,
ReasoningSummaryVerbosity = ResponseReasoningSummaryVerbosity.Auto,
},
};
options.InputItems.Add(ResponseItem.CreateUserMessageItem("What is the capital of France?"));
ResponseResult response = await client.CreateResponseAsync(options);
foreach (ReasoningResponseItem reasoning in response.OutputItems.OfType())
{
Console.WriteLine(reasoning.GetSummaryText());
}
Console.WriteLine(response.GetOutputText());
```
```ruby
require "openai"
client = OpenAI::Client.new
response = client.responses.create(
model: "gpt-6-astra",
input: "What is the capital of France?",
reasoning: {effort: :low, summary: :auto}
)
puts(response.output)
```
```bash
curl https://api.openai.com/v1/responses \
-H "Content-Type: application/json" \
-H "Authorization: Bearer $OPENAI_API_KEY" \
-d '{
"model": "gpt-6-astra",
"input": "What is the capital of France?",
"reasoning": {
"effort": "low",
"summary": "auto"
}
}'
```
This API request will return an output array with both an assistant message and a summary of the model's reasoning in generating that response.
```json
[
{
"id": "rs_6876cf02e0bc8192b74af0fb64b715ff06fa2fcced15a5ac",
"type": "reasoning",
"summary": [
{
"type": "summary_text",
"text": "**Answering a simple question**\n\nI\u2019m looking at a straightforward question: the capital of France is Paris. It\u2019s a well-known fact, and I want to keep it brief and to the point. Paris is known for its history, art, and culture, so it might be nice to add just a hint of that charm. But mostly, I\u2019ll aim to focus on delivering a clear and direct answer, ensuring the user gets what they\u2019re looking for without any extra fluff."
}
]
},
{
"id": "msg_6876cf054f58819284ecc1058131305506fa2fcced15a5ac",
"type": "message",
"status": "completed",
"content": [
{
"type": "output_text",
"annotations": [],
"logprobs": [],
"text": "The capital of France is Paris."
}
],
"role": "assistant"
}
]
```
Before using summarizers with our latest reasoning models, you may need to
complete [organization
verification](https://help.openai.com/en/articles/10910291-api-organization-verification)
to ensure safe deployment. Get started with verification on the [platform
settings page](https://platform.openai.com/settings/organization/general).
## `phase` parameter
For long-running or tool-heavy flows with GPT-5.5 and GPT-5.4 in the Responses API, use the assistant message `phase` field to avoid early stopping and other misbehavior.
`phase` is optional at the API level, but OpenAI recommends using it. Use `phase: "commentary"` for intermediate assistant updates, such as preambles before tool calls, and `phase: "final_answer"` for the completed answer. Don't add `phase` to user messages.
Using `previous_response_id` is usually the simplest path because prior assistant state is preserved. If you replay assistant history manually, preserve each original `phase` value.
Missing or dropped `phase` can cause preambles to be treated as final answers in those workflows. For model-specific prompt guidance, see [Prompting GPT-5.5](https://developers.openai.com/api/docs/guides/latest-model?model=gpt-5.5#prompting-best-practices).
### Round-trip assistant phase values
Round-trip assistant phase values
```javascript
import OpenAI from "openai";
const client = new OpenAI();
const response = await client.responses.create({
model: "gpt-6-astra",
input: [
{
role: "assistant",
phase: "commentary",
content:
"I’ll inspect the logs and then summarize root cause and remediation.",
},
{
role: "assistant",
phase: "final_answer",
content: "Root cause: cache invalidation race.",
},
{
role: "user",
content: "Great—now give me a rollout-safe fix plan.",
},
],
});
console.log(response.output_text);
```
```python
from openai import OpenAI
client = OpenAI()
response = client.responses.create(
model="gpt-6-astra",
input=[
{
"role": "assistant",
"phase": "commentary",
"content": "I’ll inspect the logs and then summarize root cause and remediation.",
},
{
"role": "assistant",
"phase": "final_answer",
"content": "Root cause: cache invalidation race.",
},
{
"role": "user",
"content": "Great—now give me a rollout-safe fix plan.",
},
],
)
print(response.output_text)
```
```go
package main
import (
"context"
"fmt"
"github.com/openai/openai-go/v3"
"github.com/openai/openai-go/v3/responses"
)
func main() {
client := openai.NewClient()
commentary := responses.ResponseInputItemParamOfMessage(
"I’ll inspect the logs and then summarize root cause and remediation.",
responses.EasyInputMessageRoleAssistant,
)
commentary.OfMessage.Phase = responses.EasyInputMessagePhaseCommentary
finalAnswer := responses.ResponseInputItemParamOfMessage(
"Root cause: cache invalidation race.",
responses.EasyInputMessageRoleAssistant,
)
finalAnswer.OfMessage.Phase = responses.EasyInputMessagePhaseFinalAnswer
response, err := client.Responses.New(context.Background(), responses.ResponseNewParams{
Model: "gpt-6-astra",
Input: responses.ResponseNewParamsInputUnion{OfInputItemList: responses.ResponseInputParam{
commentary,
finalAnswer,
responses.ResponseInputItemParamOfMessage("Great—now give me a rollout-safe fix plan.", responses.EasyInputMessageRoleUser),
}},
})
if err != nil {
panic(err)
}
fmt.Println(response.OutputText())
}
```
```java
import com.openai.client.OpenAIClient;
import com.openai.client.okhttp.OpenAIOkHttpClient;
import com.openai.models.responses.EasyInputMessage;
import com.openai.models.responses.ResponseCreateParams;
import com.openai.models.responses.ResponseInputItem;
import java.util.List;
ResponseCreateParams params =
ResponseCreateParams.builder()
.model("gpt-6-astra")
.inputOfResponse(
List.of(
ResponseInputItem.ofEasyInputMessage(
EasyInputMessage.builder()
.role(EasyInputMessage.Role.ASSISTANT)
.phase(EasyInputMessage.Phase.COMMENTARY)
.content(
"I'll inspect the logs and then summarize root cause and remediation.")
.build()),
ResponseInputItem.ofEasyInputMessage(
EasyInputMessage.builder()
.role(EasyInputMessage.Role.ASSISTANT)
.phase(EasyInputMessage.Phase.FINAL_ANSWER)
.content("Root cause: cache invalidation race.")
.build()),
ResponseInputItem.ofEasyInputMessage(
EasyInputMessage.builder()
.role(EasyInputMessage.Role.USER)
.content("Great—now give me a rollout-safe fix plan.")
.build())))
.build();
client.responses().create(params).output().stream()
.flatMap(item -> item.message().stream())
.flatMap(message -> message.content().stream())
.flatMap(content -> content.outputText().stream())
.forEach(text -> System.out.println(text.text()));
```
```ruby
require "openai"
client = OpenAI::Client.new
response = client.responses.create(
model: "gpt-6-astra",
input: [
{
role: :assistant,
phase: :commentary,
content: "I'll inspect the logs and then summarize root cause and remediation."
},
{
role: :assistant,
phase: :final_answer,
content: "Root cause: cache invalidation race."
},
{
role: :user,
content: "Great—now give me a rollout-safe fix plan."
}
]
)
puts(response.output_text)
```
## Advice on prompting
Consider these differences when prompting a reasoning model. Reasoning-capable GPT-5 models usually work best when you give them a clear goal, strong constraints, and an explicit output contract without prescribing every intermediate step.
- Give the model the task, constraints, and desired output format.
- Treat `reasoning.effort` as a tuning knob, not the primary way to recover quality.
- For agentic or research-heavy workflows, define what counts as done and how the model should verify its work.
For more information on best practices when using reasoning models, [refer to this guide](https://developers.openai.com/api/docs/guides/reasoning-best-practices).
### Prompt examples
Coding (refactoring)
OpenAI o-series models are able to implement complex algorithms and produce code. This prompt asks o1 to refactor a React component based on some specific criteria.
Refactor code
```javascript
import OpenAI from "openai";
const openai = new OpenAI();
const prompt = `
Instructions:
- Given the React component below, change it so that nonfiction books have red
text.
- Return only the code in your reply
- Do not include any additional formatting, such as markdown code blocks
- For formatting, use four space tabs, and do not allow any lines of code to
exceed 80 columns
const books = [
{ title: 'Dune', category: 'fiction', id: 1 },
{ title: 'Frankenstein', category: 'fiction', id: 2 },
{ title: 'Moneyball', category: 'nonfiction', id: 3 },
];
export default function BookList() {
const listItems = books.map(book =>
{book.title}
);
return (
);
}
`.trim();
const response = await openai.responses.create({
model: "gpt-6-astra",
input: [
{
role: "user",
content: prompt,
},
],
});
console.log(response.output_text);
```
```python
from openai import OpenAI
client = OpenAI()
prompt = """
Instructions:
- Given the React component below, change it so that nonfiction books have red
text.
- Return only the code in your reply
- Do not include any additional formatting, such as markdown code blocks
- For formatting, use four space tabs, and do not allow any lines of code to
exceed 80 columns
const books = [
{ title: 'Dune', category: 'fiction', id: 1 },
{ title: 'Frankenstein', category: 'fiction', id: 2 },
{ title: 'Moneyball', category: 'nonfiction', id: 3 },
];
export default function BookList() {
const listItems = books.map(book =>
{book.title}
);
return (
);
}
"""
response = client.responses.create(
model="gpt-6-astra",
input=[
{
"role": "user",
"content": prompt,
}
],
)
print(response.output_text)
```
```go
package main
import (
"context"
"fmt"
"github.com/openai/openai-go/v3"
"github.com/openai/openai-go/v3/responses"
)
func main() {
client := openai.NewClient()
prompt := `Instructions:
- Given the React component below, change it so that nonfiction books have red text.
- Return only the code in your reply.
- Do not include any additional formatting, such as markdown code blocks.
const books = [
{ title: 'Dune', category: 'fiction', id: 1 },
{ title: 'Frankenstein', category: 'fiction', id: 2 },
{ title: 'Moneyball', category: 'nonfiction', id: 3 },
];`
response, err := client.Responses.New(context.Background(), responses.ResponseNewParams{
Model: "gpt-6-astra",
Input: responses.ResponseNewParamsInputUnion{
OfString: openai.String(prompt),
},
})
if err != nil {
panic(err)
}
fmt.Println(response.OutputText())
}
```
```java
import com.openai.client.OpenAIClient;
import com.openai.client.okhttp.OpenAIOkHttpClient;
import com.openai.models.responses.ResponseCreateParams;
String prompt =
"""
Instructions:
- Given the React component below, change it so that nonfiction books have red text.
- Return only the code in your reply.
- Do not include any additional formatting, such as markdown code blocks.
const books = [
{ title: 'Dune', category: 'fiction', id: 1 },
{ title: 'Frankenstein', category: 'fiction', id: 2 },
{ title: 'Moneyball', category: 'nonfiction', id: 3 },
];
"""
.strip();
ResponseCreateParams params =
ResponseCreateParams.builder().model("gpt-6-astra").input(prompt).build();
client.responses().create(params).output().stream()
.flatMap(item -> item.message().stream())
.flatMap(message -> message.content().stream())
.flatMap(content -> content.outputText().stream())
.forEach(text -> System.out.println(text.text()));
```
```csharp
using OpenAI.Responses;
#pragma warning disable OPENAI001
string key = Environment.GetEnvironmentVariable("OPENAI_API_KEY")!;
ResponsesClient client = new(key);
string prompt =
"""
Instructions:
- Given the React component below, make nonfiction book titles red.
- Return only the updated component code in your reply.
- Do not include any additional formatting, such as markdown code blocks.
- For formatting, use four space tabs, and do not allow any lines of code to
exceed 80 columns.
const books = [
{ title: 'Dune', category: 'fiction', id: 1 },
{ title: 'Frankenstein', category: 'fiction', id: 2 },
{ title: 'Moneyball', category: 'nonfiction', id: 3 },
];
export default function BookList() {
const listItems = books.map(book =>
{book.title}
);
return (
);
}
""";
ResponseResult response = await client.CreateResponseAsync(
"gpt-6-astra",
[ResponseItem.CreateUserMessageItem(prompt)]
);
Console.WriteLine(response.GetOutputText());
```
```ruby
require "openai"
client = OpenAI::Client.new
prompt = <<~PROMPT
Instructions:
- Given the React component below, change it so that nonfiction books have red text.
- Return only the code in your reply.
- Do not include any additional formatting, such as markdown code blocks.
const books = [
{ title: 'Dune', category: 'fiction', id: 1 },
{ title: 'Frankenstein', category: 'fiction', id: 2 },
{ title: 'Moneyball', category: 'nonfiction', id: 3 },
];
PROMPT
response = client.responses.create(
model: "gpt-6-astra",
input: prompt
)
puts(response.output_text)
```
Coding (planning)
OpenAI o-series models are also adept in creating multi-step plans. This example prompt asks o1 to create a filesystem structure for a full solution, along with Python code that implements the desired use case.
Plan and create a Python project
```javascript
import OpenAI from "openai";
const openai = new OpenAI();
const prompt = `
I want to build a Python app that takes user questions and looks
them up in a database where they are mapped to answers. If there
is close match, it retrieves the matched answer. If there isn't,
it asks the user to provide an answer and stores the
question/answer pair in the database. Make a plan for the directory
structure you'll need, then return each file in full. Only supply
your reasoning at the beginning and end, not throughout the code.
`.trim();
const response = await openai.responses.create({
model: "gpt-6-astra",
input: [
{
role: "user",
content: prompt,
},
],
});
console.log(response.output_text);
```
```python
from openai import OpenAI
client = OpenAI()
prompt = """
I want to build a Python app that takes user questions and looks
them up in a database where they are mapped to answers. If there
is close match, it retrieves the matched answer. If there isn't,
it asks the user to provide an answer and stores the
question/answer pair in the database. Make a plan for the directory
structure you'll need, then return each file in full. Only supply
your reasoning at the beginning and end, not throughout the code.
"""
response = client.responses.create(
model="gpt-6-astra",
input=[
{
"role": "user",
"content": prompt,
}
],
)
print(response.output_text)
```
```go
package main
import (
"context"
"fmt"
"github.com/openai/openai-go/v3"
"github.com/openai/openai-go/v3/responses"
)
func main() {
client := openai.NewClient()
prompt := `I want to build a Python app that takes user questions and looks them up
in a database where they are mapped to answers. If there is a close match, it
retrieves the matched answer. If there is not, it asks the user to provide an
answer and stores the question/answer pair in the database. Make a plan for the
directory structure you will need, then return each file in full.`
response, err := client.Responses.New(context.Background(), responses.ResponseNewParams{
Model: "gpt-6-astra",
Input: responses.ResponseNewParamsInputUnion{
OfString: openai.String(prompt),
},
})
if err != nil {
panic(err)
}
fmt.Println(response.OutputText())
}
```
```java
import com.openai.client.OpenAIClient;
import com.openai.client.okhttp.OpenAIOkHttpClient;
import com.openai.models.responses.ResponseCreateParams;
String prompt =
"""
I want to build a Python app that looks up user questions in a database where
they are mapped to answers. If there is a close match, it retrieves the answer.
Otherwise, it asks the user for an answer and stores the question and answer.
Plan the directory structure, then return each file in full.
"""
.strip();
ResponseCreateParams params =
ResponseCreateParams.builder().model("gpt-6-astra").input(prompt).build();
client.responses().create(params).output().stream()
.flatMap(item -> item.message().stream())
.flatMap(message -> message.content().stream())
.flatMap(content -> content.outputText().stream())
.forEach(text -> System.out.println(text.text()));
```
```csharp
using OpenAI.Responses;
#pragma warning disable OPENAI001
string key = Environment.GetEnvironmentVariable("OPENAI_API_KEY")!;
ResponsesClient client = new(key);
string prompt =
"""
I want to build a Python app that looks up user questions in a database where
they are mapped to answers. If there is a close match, it retrieves the answer.
Otherwise, it asks the user for an answer and stores the question and answer.
Plan the directory structure, then return each file in full.
Only supply your reasoning at the beginning and end, not throughout the code.
""";
ResponseResult response = await client.CreateResponseAsync("gpt-6-astra", prompt);
Console.WriteLine(response.GetOutputText());
```
```ruby
require "openai"
client = OpenAI::Client.new
prompt = <<~PROMPT
I want to build a Python app that looks up user questions in a database where
they are mapped to answers. If there is a close match, it retrieves the answer.
Otherwise, it asks the user for an answer and stores the question and answer.
Plan the directory structure, then return each file in full.
PROMPT
response = client.responses.create(
model: "gpt-6-astra",
input: prompt
)
puts(response.output_text)
```
STEM Research
OpenAI o-series models have shown excellent performance in STEM research. Prompts asking for support of basic research tasks should show strong results.
Ask questions related to basic scientific research
```javascript
import OpenAI from "openai";
const openai = new OpenAI();
const prompt = `
What are three compounds we should consider investigating to
advance research into new antibiotics? Why should we consider
them?
`;
const response = await openai.responses.create({
model: "gpt-6-astra",
input: [
{
role: "user",
content: prompt,
},
],
});
console.log(response.output_text);
```
```python
from openai import OpenAI
client = OpenAI()
prompt = """
What are three compounds we should consider investigating to
advance research into new antibiotics? Why should we consider
them?
"""
response = client.responses.create(
model="gpt-6-astra", input=[{"role": "user", "content": prompt}]
)
print(response.output_text)
```
```go
package main
import (
"context"
"fmt"
"github.com/openai/openai-go/v3"
"github.com/openai/openai-go/v3/responses"
)
func main() {
client := openai.NewClient()
prompt := `What are three compounds we should consider investigating to advance
research into new antibiotics? Why should we consider them?`
response, err := client.Responses.New(context.Background(), responses.ResponseNewParams{
Model: "gpt-6-astra",
Input: responses.ResponseNewParamsInputUnion{
OfString: openai.String(prompt),
},
})
if err != nil {
panic(err)
}
fmt.Println(response.OutputText())
}
```
```java
import com.openai.client.OpenAIClient;
import com.openai.client.okhttp.OpenAIOkHttpClient;
import com.openai.models.responses.ResponseCreateParams;
String prompt =
"""
What are three compounds we should consider investigating to advance research
into new antibiotics? Why should we consider them?
"""
.strip();
ResponseCreateParams params =
ResponseCreateParams.builder().model("gpt-6-astra").input(prompt).build();
client.responses().create(params).output().stream()
.flatMap(item -> item.message().stream())
.flatMap(message -> message.content().stream())
.flatMap(content -> content.outputText().stream())
.forEach(text -> System.out.println(text.text()));
```
```csharp
using OpenAI.Responses;
#pragma warning disable OPENAI001
string key = Environment.GetEnvironmentVariable("OPENAI_API_KEY")!;
ResponsesClient client = new(key);
string prompt =
"""
What are three compounds we should investigate to advance research into
new antibiotics? Why should we consider them?
""";
ResponseResult response = await client.CreateResponseAsync(
"gpt-6-astra",
[ResponseItem.CreateUserMessageItem(prompt)]
);
Console.WriteLine(response.GetOutputText());
```
```ruby
require "openai"
client = OpenAI::Client.new
prompt = <<~PROMPT
What are three compounds we should consider investigating to advance research
into new antibiotics? Why should we consider them?
PROMPT
response = client.responses.create(
model: "gpt-6-astra",
input: prompt
)
puts(response.output_text)
```
## Use case examples
Some examples of using reasoning models for real-world use cases can be found in [the cookbook](https://developers.openai.com/cookbook).
[Using reasoning for data validation
Evaluate a synthetic medical data set for discrepancies.](https://developers.openai.com/cookbook/examples/o1/using_reasoning_for_data_validation)
[Using reasoning for routine generation
Use help center articles to generate actions that an agent could perform.](https://developers.openai.com/cookbook/examples/o1/using_reasoning_for_routine_generation)