Context Engineering(Bonigarcia 教程)
Local retrieval-augmented generation (RAG)
This sample application implements a local RAG system using the following stack:
- LLM: Llama 3.2 1B via Ollama
- Embedding model: Nomic Embed Text (embedder for OllamaEmbedder)
- Vector database: Qdrant
- Agent framework: Agno
Requirements
To run this example, you need the following:
- Python, for the local RAG.
- Ollama, for the LLM and the embedding model.
- Docker, for the vector database.
- Node.js, for the agent web interface.
Steps for running this example
- Pull Llama 3.2 1B and Nomic Embed Text with Ollama:
bash
ollama pull llama3.2:1b
ollama pull nomic-embed-text- Pull and install Qdrant with Docker:
bash
docker pull qdrant/qdrant
docker run -p 6333:6333 qdrant/qdrant- Install dependencies:
bash
python -m venv .venv

# macOS/Linux:
source .venv/bin/activate

# Windows Command Prompt:
.venv\Scripts\activate.bat

# Windows PowerShell:
.venv\Scripts\Activate.ps1

pip install -r requirements.txt- Run the script. Check that the agent API interface is working at http://localhost:7777/
bash
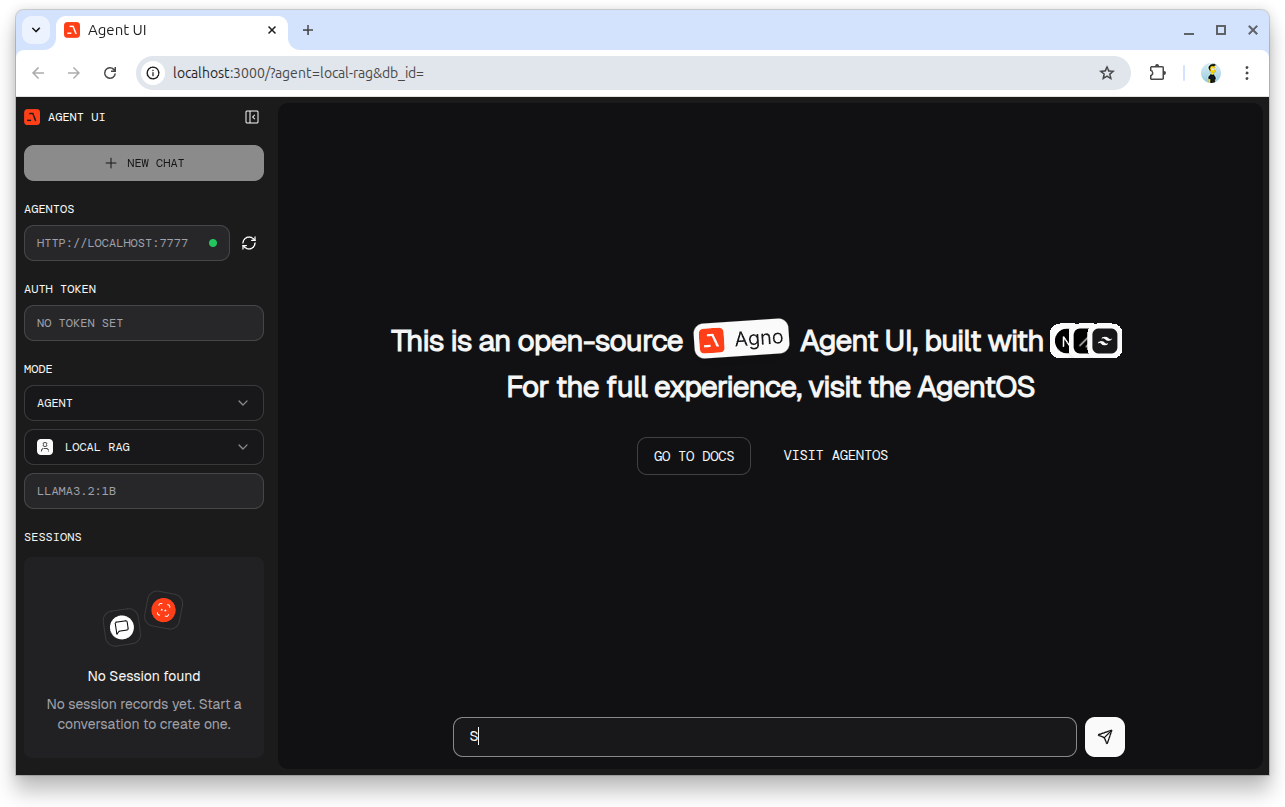
python local_rag.py- Install a web interface. Open the UI interface and interact with the agent at http://localhost:3000/
bash
npx create-agent-ui@latest
cd agent-ui
npm install
npm run dev