GRPO Fine-tuning on Fireworks Training API
This project demonstrates how to fine-tune Qwen3-8B for structured JSON invoice extraction using GRPO (Group Relative Policy Optimization) via the Fireworks Training API. The training loop runs from a local notebook. The model trains on remote GPUs managed by Fireworks.
The fine-tuned model scores 82% schema-valid accuracy on a held-out eval set, beating both the base Qwen3-8B (62%) and GPT-4.1 (58%) on the same task.
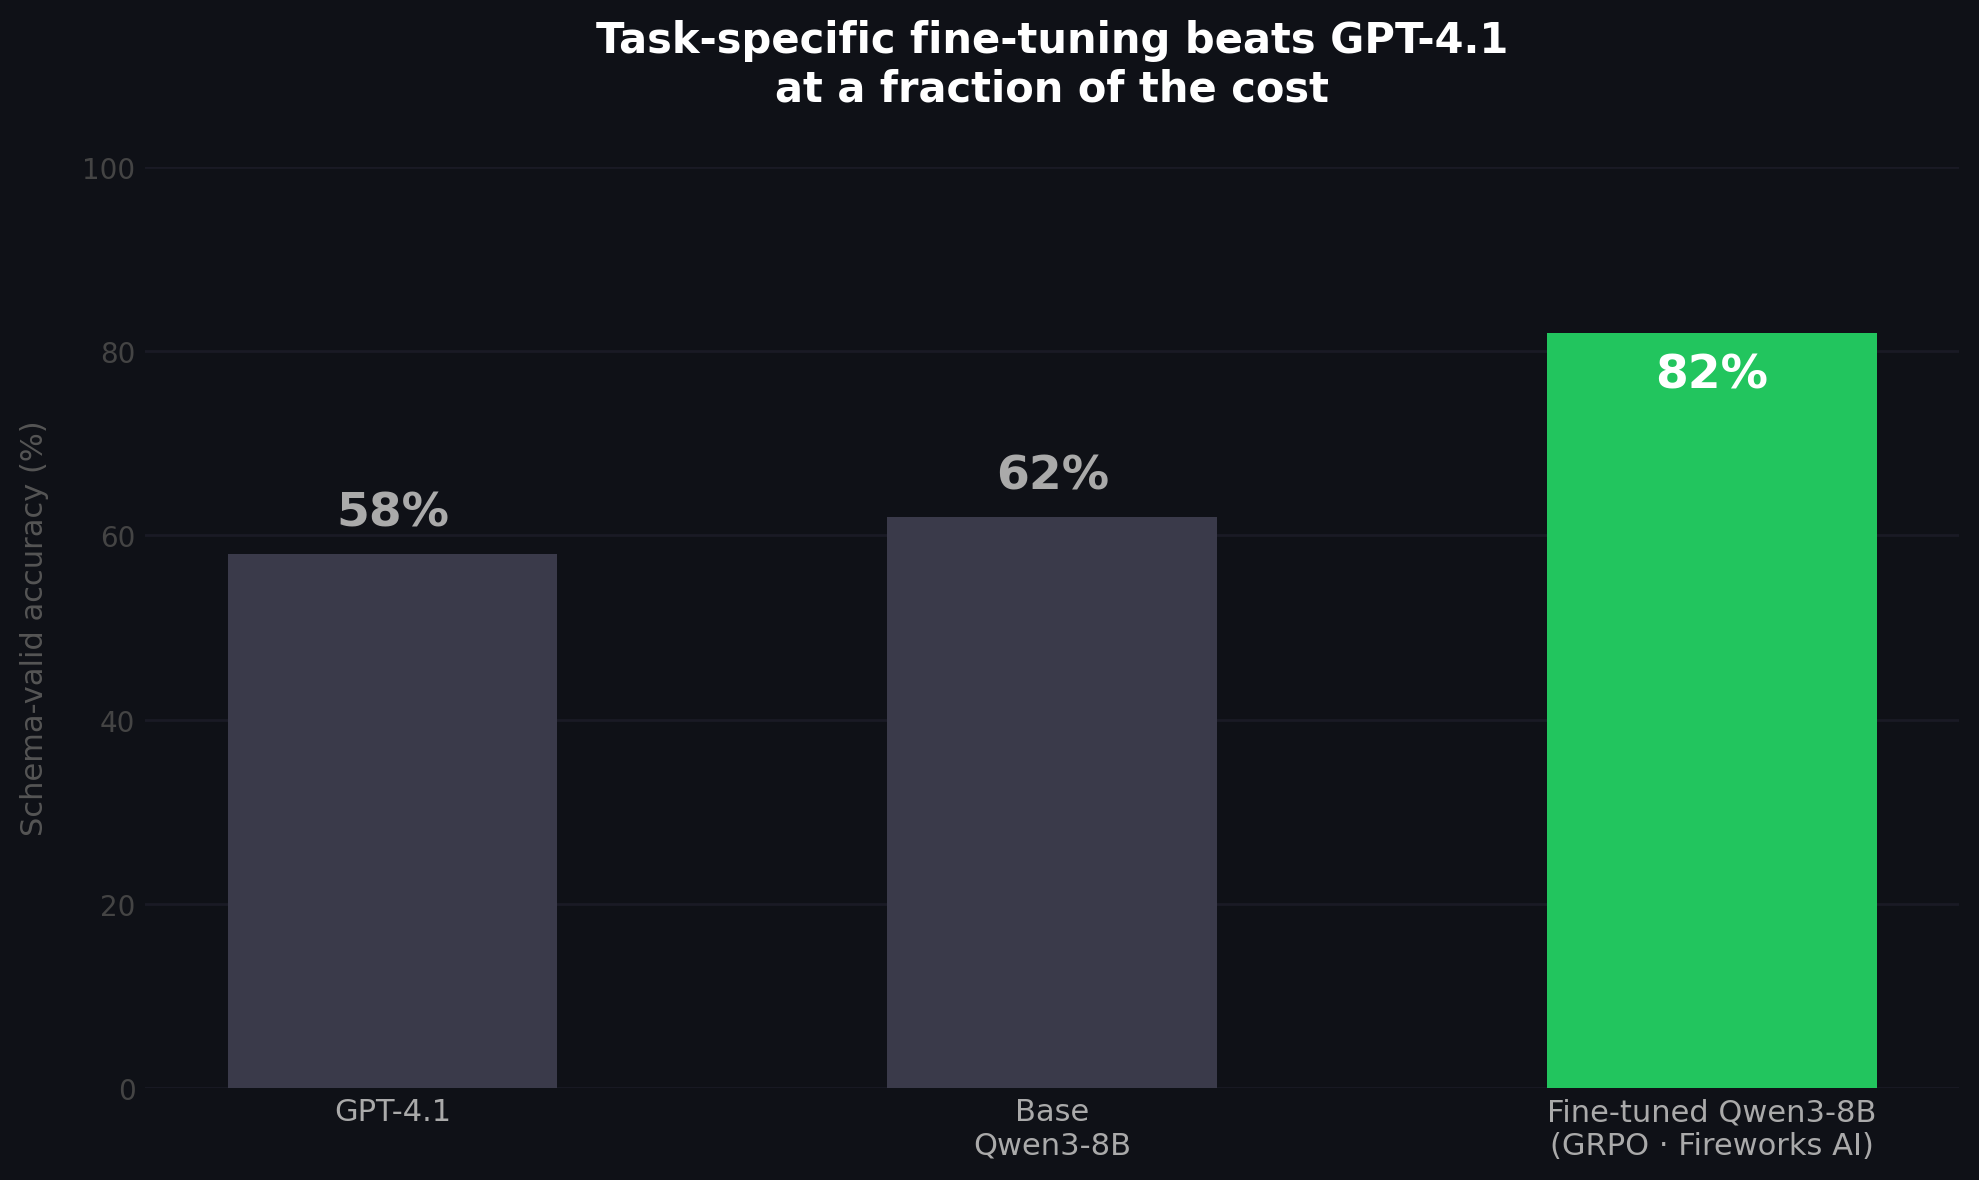
Setup and installations
Get API Keys:
- Fireworks AI — needed for training and inference. Requires RLOR (training) access. Store it as
FIREWORKS_API_KEYin a.envfile. - OpenRouter — needed for base model and GPT-4.1 eval. Store it as
OPENROUTER_API_KEYin a.envfile.
Refer to .env.example for the structure of the file. You will also need your Fireworks account ID stored as FIREWORKS_ACCOUNT_ID.
Clone the Fireworks cookbook:
git clone https://github.com/fw-ai/cookbook.gitInstall Dependencies:
Ensure you have Python 3.10 or later installed.
uv venv
source .venv/bin/activate
uv pip install python-dotenv jsonschema openai fireworks-ai matplotlib
uv pip install -e "cookbook/training[training]"
uv pip install eval-protocol nest_asyncio
Select the virtual environment as the kernel in the notebook.
Run the notebook:
Open and run grpo_json_extraction.ipynb end-to-end. The notebook covers:
- Reward function that scores JSON completions against a schema
- Dataset upload to Fireworks
- GRPO training loop against remote GPUs
- Baseline eval on base Qwen3-8B
- Post-training eval on the fine-tuned model
- GPT-4.1 comparison eval
- Inference on the deployed model
Agent Skill
The agent-skill/grpo-finetune/ folder contains a reusable agent skill that wraps the full GRPO fine-tuning pipeline — from reward validation to dataset upload to training to inference — into a single runnable script.
What's included:
run_pipeline.py— end-to-end pipeline: validates reward, uploads dataset, runs GRPO training, evals the fine-tuned model, and runs sample inferencegenerate_reward.py— validates that yourreward.pysatisfies the scoring contract before any GPU spendagent_demo.py— runs the deployed fine-tuned model on sample invoices and prints structured extraction resultsSKILL.md— skill definition for Claude Code; describes when and how to trigger the skill
Run the pipeline:
python agent-skill/grpo-finetune/run_pipeline.py \
    --train ./train_prompts.jsonl \
    --eval  ./eval_prompts.jsonl \
    --task  invoice-extraction \