Switching models mid-conversation
Claude Fable 5.1 and Claude Mythos 5.1 read thinking blocks produced by each other and by earlier Claude models. No earlier model reads thinking blocks from Claude Fable 5.1 or Claude Mythos 5.1.
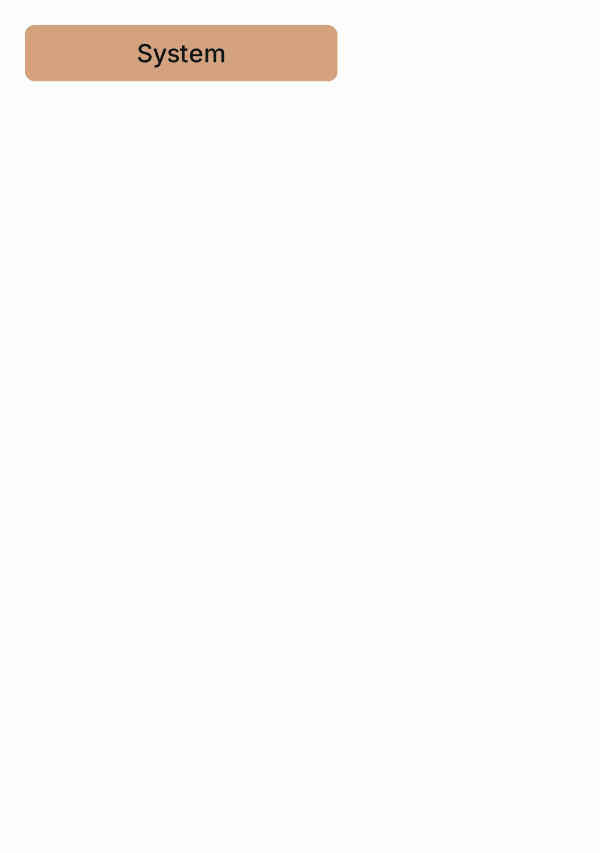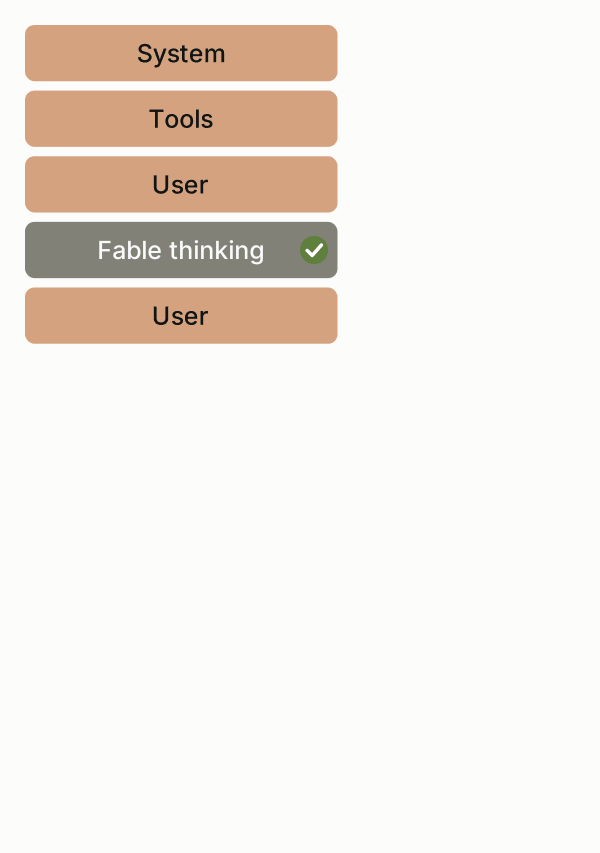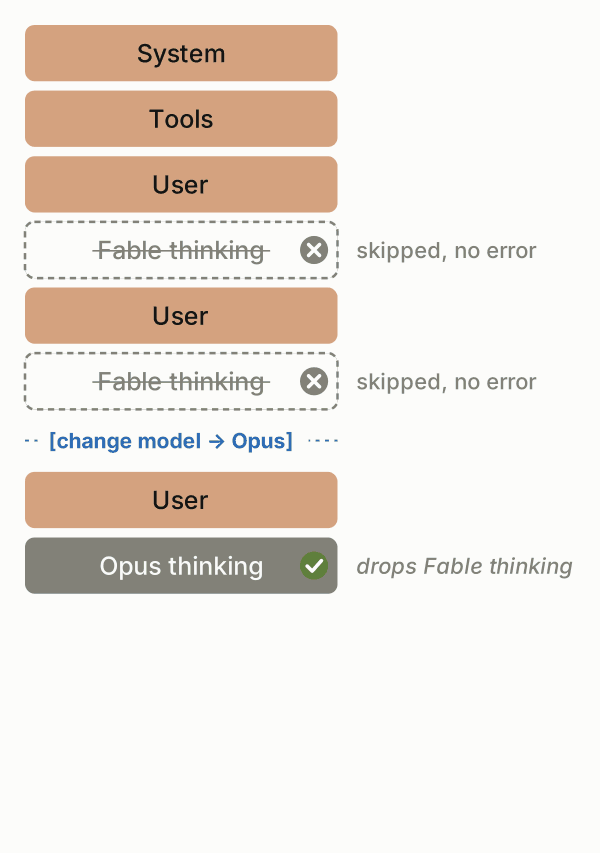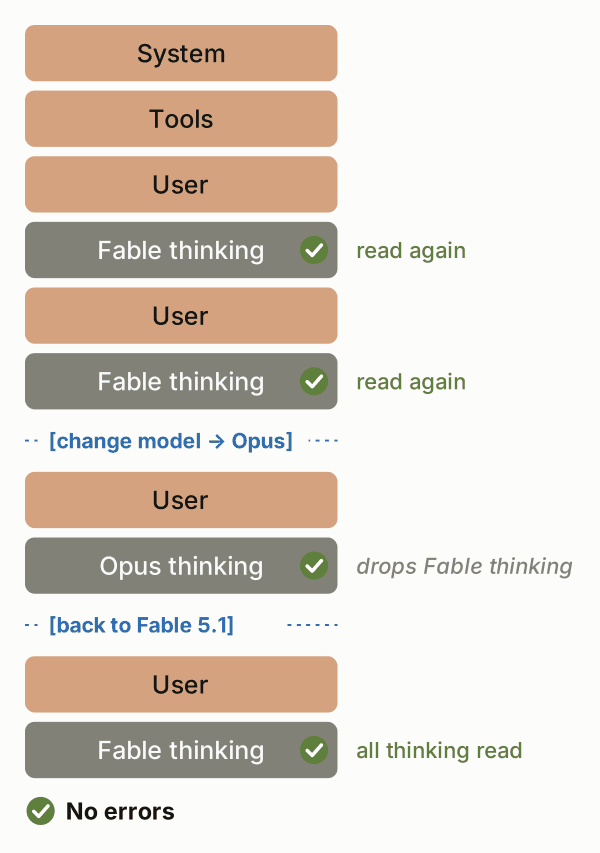
- A conversation that moves up to Claude Fable 5.1 keeps its reasoning. The earlier model's thinking blocks stay readable, so the model thinks as usual from the first turn after the switch.
- A conversation that moves down to an earlier model loses Claude Fable 5.1's reasoning for that request. This happens when a router sends a turn to a cheaper model, after a classifier refusal fallback, or during a server-side fallback. The API removes the unreadable blocks before the prompt reaches the model. They aren't billed and don't count toward
input_tokens.
Keep sending the full history on every request, thinking blocks included, and let the API drop what the current model can't read. The API never edits your messages array, so the dropped blocks stay in your history. When the same history goes back to Claude Fable 5.1, its blocks are readable again, along with the earlier model's thinking. The reasoning is lost for good only if your client removes the blocks itself, for example a harness that strips thinking on a model switch or rebuilds the history from what each model used.
With the thinking-binding-controls-2026-08-01 beta header, the response lists each dropped block in a top-level input_transformations array with reason: "model_binding_mismatch":
{
  "input_transformations": [
    {
      "type": "thinking_dropped",
      "path": "messages.3.content.0",
      "reason": "model_binding_mismatch"
    }
  ]
}
Without the header, the drop is silent. This entry isn't a bug in your integration, and prefix_mismatch_behavior has no effect on it: a block the current model can't read is always dropped.